
family of lightweight open models designed by Google

github.com Oct 19
Community benchmark: v0.0.3 · Issue #2 · hardenedlinux/SonicBoom: Thank you for helping! This issue collects results for v0.0.3 only. It will be locked when the ...
github.com/hardenedlinux/SonicBoom/issues/2


I found a Gemini alternative that runs completely offline on my phone: I ditched the cloud for private AI conversations
androidpolice.com/gemini-alternative-that-runs-completely-offline-on-my-phone/


My local LLM is small enough to run on my laptop, but smart enough to replace these 3 subscriptions
xda-developers.com/my-local-llm-is-small-enough-to-run-on-my-laptop-but-smart-enough-to-replace-these-x-subscriptions/

I found a Gemini alternative that runs completely offline on my phone: I ditched the cloud for private AI conversations
androidpolice.com/gemini-alternative-that-runs-completely-offline-on-my-phone/
github.com Oct 02
GitHub - cannitellinicholas-spec/PixelUnlockGPU: OpenAI-compatible on-device LiteRT-LM server for Pixel (Tensor G5) — serves Gemma to TypingMind and any OpenAI ...
github.com/cannitellinicholas-spec/PixelUnlockGPU

github.com Sep 28
GitHub - solvingSteve/Gevva0: System 0 local decision gateway powered by Gemma 4. Direct logit scoring, KV-cache sequence branching ...
github.com/solvingSteve/Gevva0

Gemma 4 runs fine on my laptop, but putting it on my NAS is what changed how I use it
xda-developers.com/gemma-4-runs-fine-on-my-laptop-but-putting-it-on-my-nas-is-what-changed-how-i-use-it/
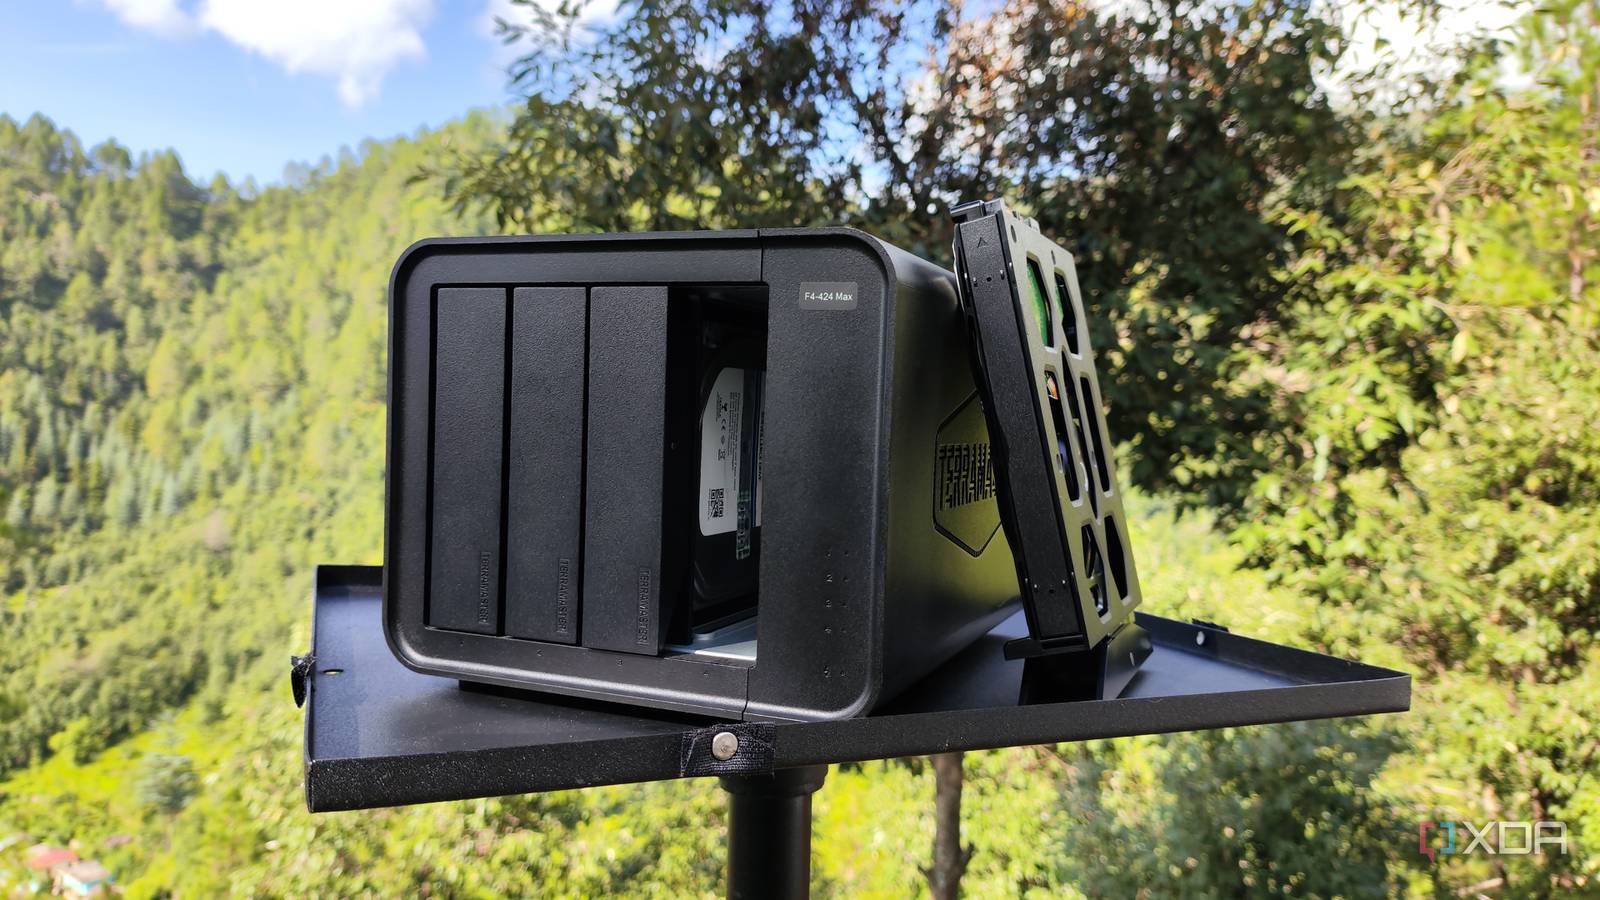
Gemma 4 runs fine on my laptop, but putting it on my NAS is what changed how I use it
xda-developers.com/gemma-4-runs-fine-on-my-laptop-but-putting-it-on-my-nas-is-what-changed-how-i-use-it/
After trying 20+ local LLMs, these are the 4 I keep installed for different jobs: My local AI setup isn’t about collecting models, it’s about having the right ...
xda-developers.com/local-llms-i-keep-installed-for-different-jobs/
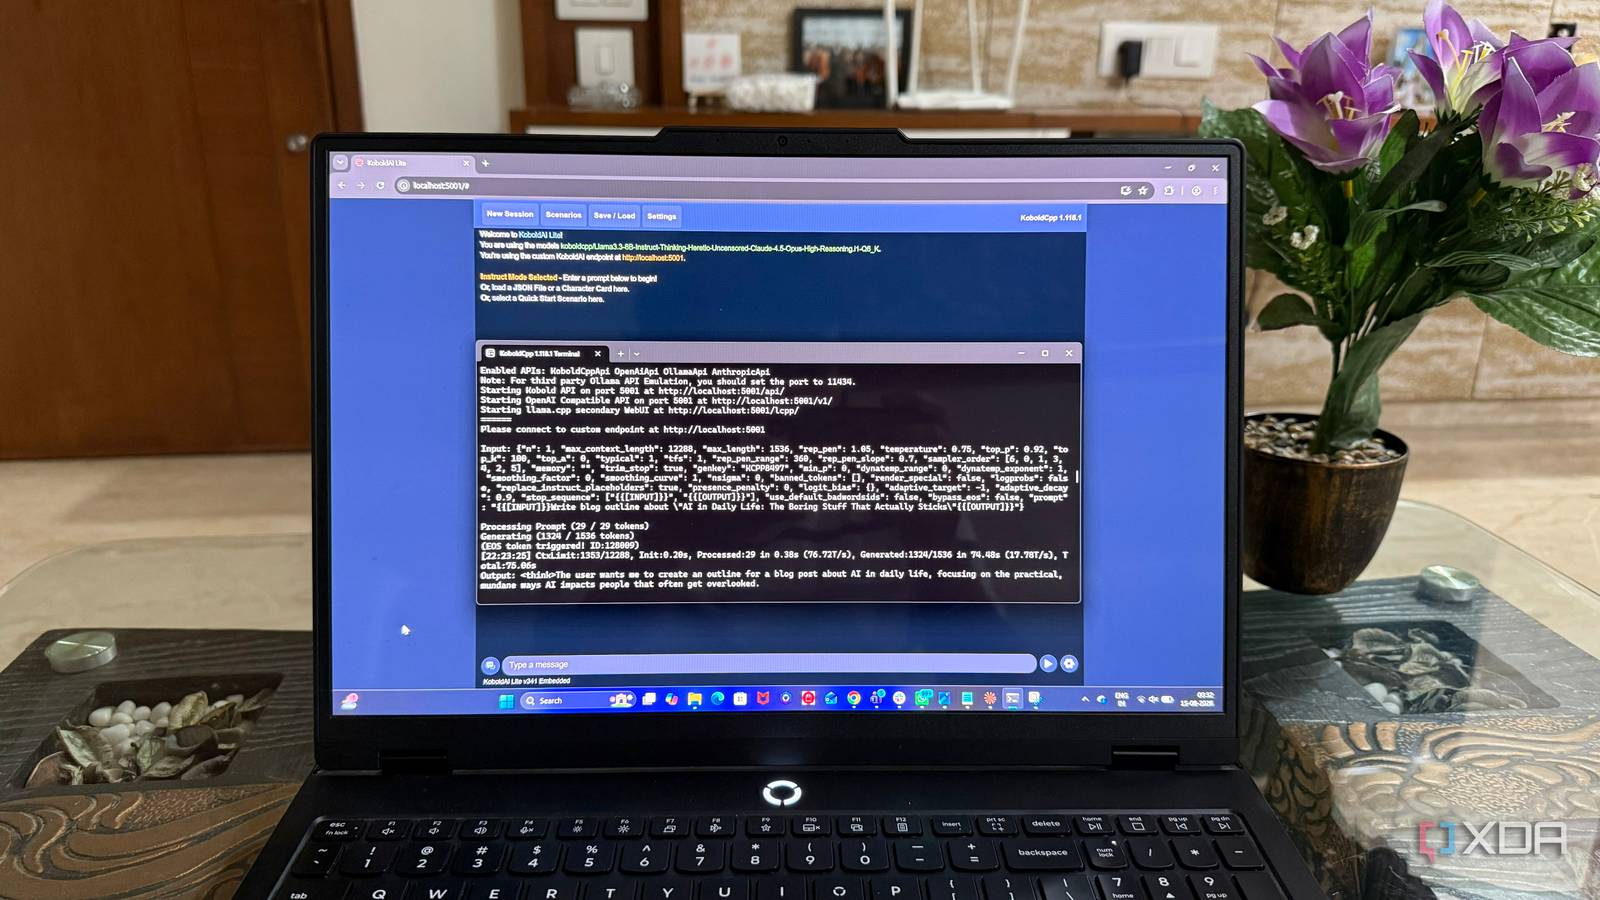
My local LLM is small enough to run on my laptop, but smart enough to replace these 3 subscriptions
xda-developers.com/my-local-llm-is-small-enough-to-run-on-my-laptop-but-smart-enough-to-replace-these-x-subscriptions/
This open-source Google app turned my phone into a fully local AI lab: A fully local AI lab in your pocket is a thing now
xda-developers.com/this-google-app-turned-my-phone-into-fully-local-ai-lab/

github.com Sep 16
GitHub - terryguo3180-eng/Gemma.c: Gemma 1/2/3 model inference in single C file, supports W8A8 quantization
github.com/terryguo3180-eng/Gemma.c

This open-source Google app turned my phone into a fully local AI lab: A fully local AI lab in your pocket is a thing now
xda-developers.com/this-google-app-turned-my-phone-into-fully-local-ai-lab/
This open-source Google app turned my phone into a fully local AI lab: A fully local AI lab in your pocket is a thing now
xda-developers.com/this-google-app-turned-my-phone-into-fully-local-ai-lab/
I tried 3 mobile local LLM apps for a month, and the least popular one does what the rest can't
xda-developers.com/tried-mobile-local-llm-apps-for-month-least-popular-one-does-what-the-rest-cant/

I revived my old Windows 10 gaming PC as a llama.cpp server, and it’s good enough to handle everyday productivity tools
xda-developers.com/i-revived-my-old-windows-10-gaming-pc-as-a-llamacpp-server/
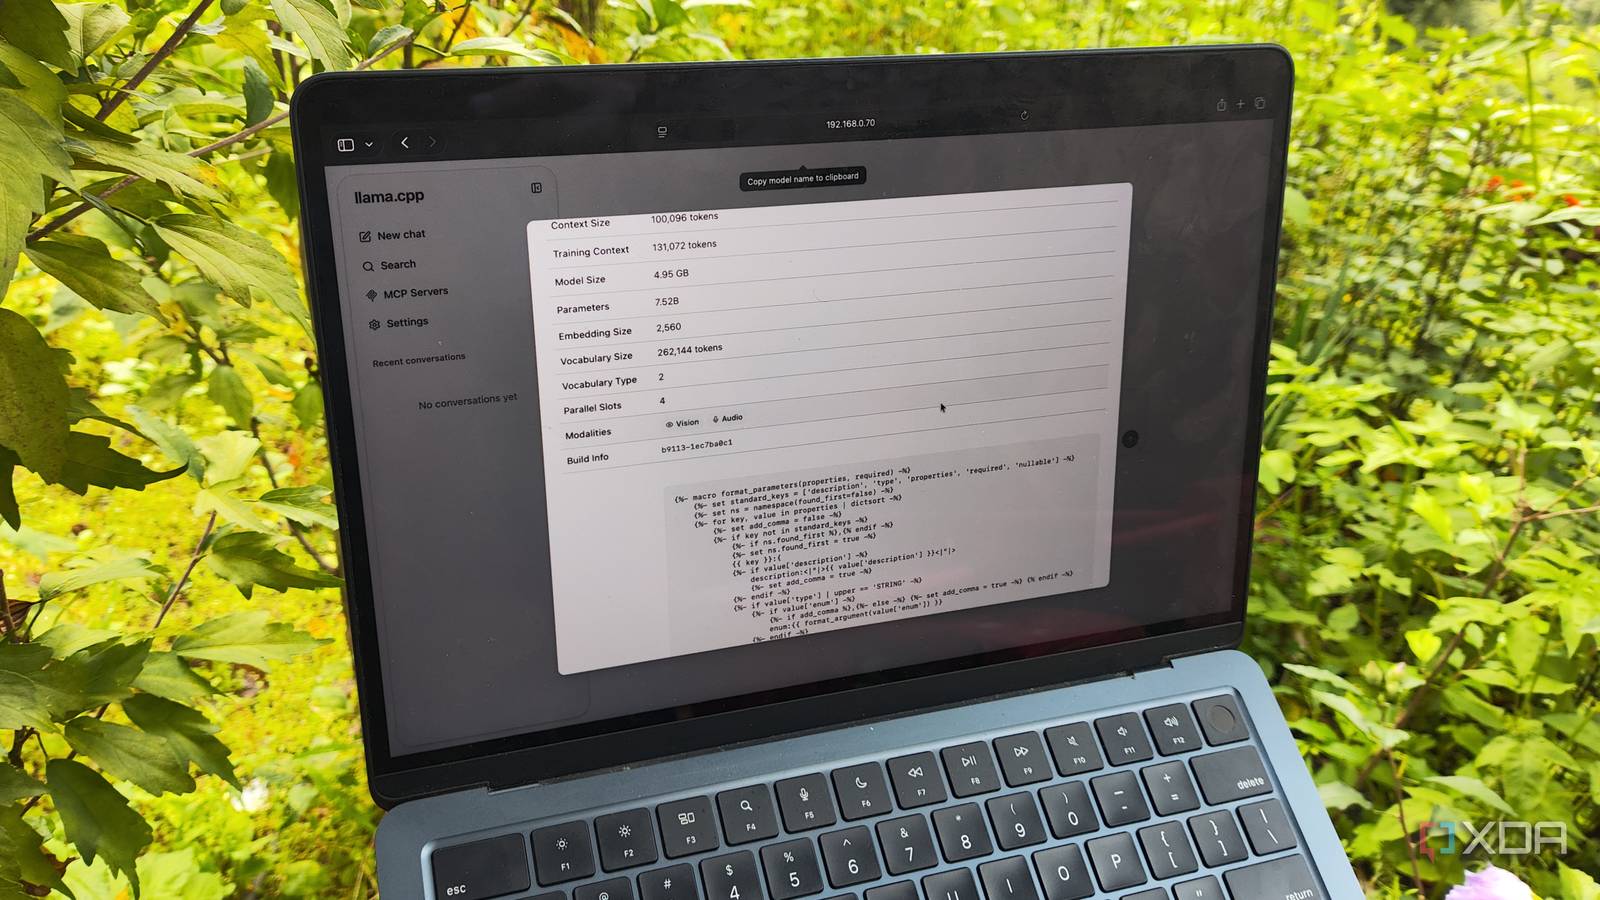
I stopped using Qwen and Gemma after finding a local LLM that actually thinks before answering
xda-developers.com/stopped-using-qwen-and-gemma-after-finding-local-llm-that-thinks-before-answering/
github.com Aug 30
GitHub - dysangel/vllm at qwen38next-sm121: A high-throughput and memory-efficient inference and serving engine for LLMs - GitHub - dysangel/vllm at ...
github.com/dysangel/vllm/tree/qwen38next-sm121


4 everyday things a local LLM does for me that I would never pay a chatbot for: Sleeping on local AI can literally cost you money
xda-developers.com/x-everyday-things-a-local-llm-does-for-me-that-i-would-never-pay-a-chatbot-for/
I run same local LLM on an RTX 5070 and integrated graphics, and the results were beyond my expectations
xda-developers.com/same-local-llm-on-rtx-5070-and-integrated-graphics/

Premsys App - App Store: Download Premsys by Premsys Inc. on the App Store. See screenshots, ratings and reviews, user tips, and more apps like Premsys.
apps.apple.com/us/app/premsys/id6791407839


I turned my phone into an AI agent powered by my local LLM, and it installed software on its own
xda-developers.com/turned-phone-ai-agent-powered-local-llm-installed-software/

No cloud, no GPUs, no problem: Liquid AI's new model LFM2.5-2.6B brings powerful AI agents to devices as small as a Raspberry Pi
venturebeat.com/technology/no-cloud-no-gpus-no-problem-liquid-ais-new-model-lfm2-5-2-6b-brings-powerful-ai-agents-to-devices-as-small-as-a-raspberry-pi
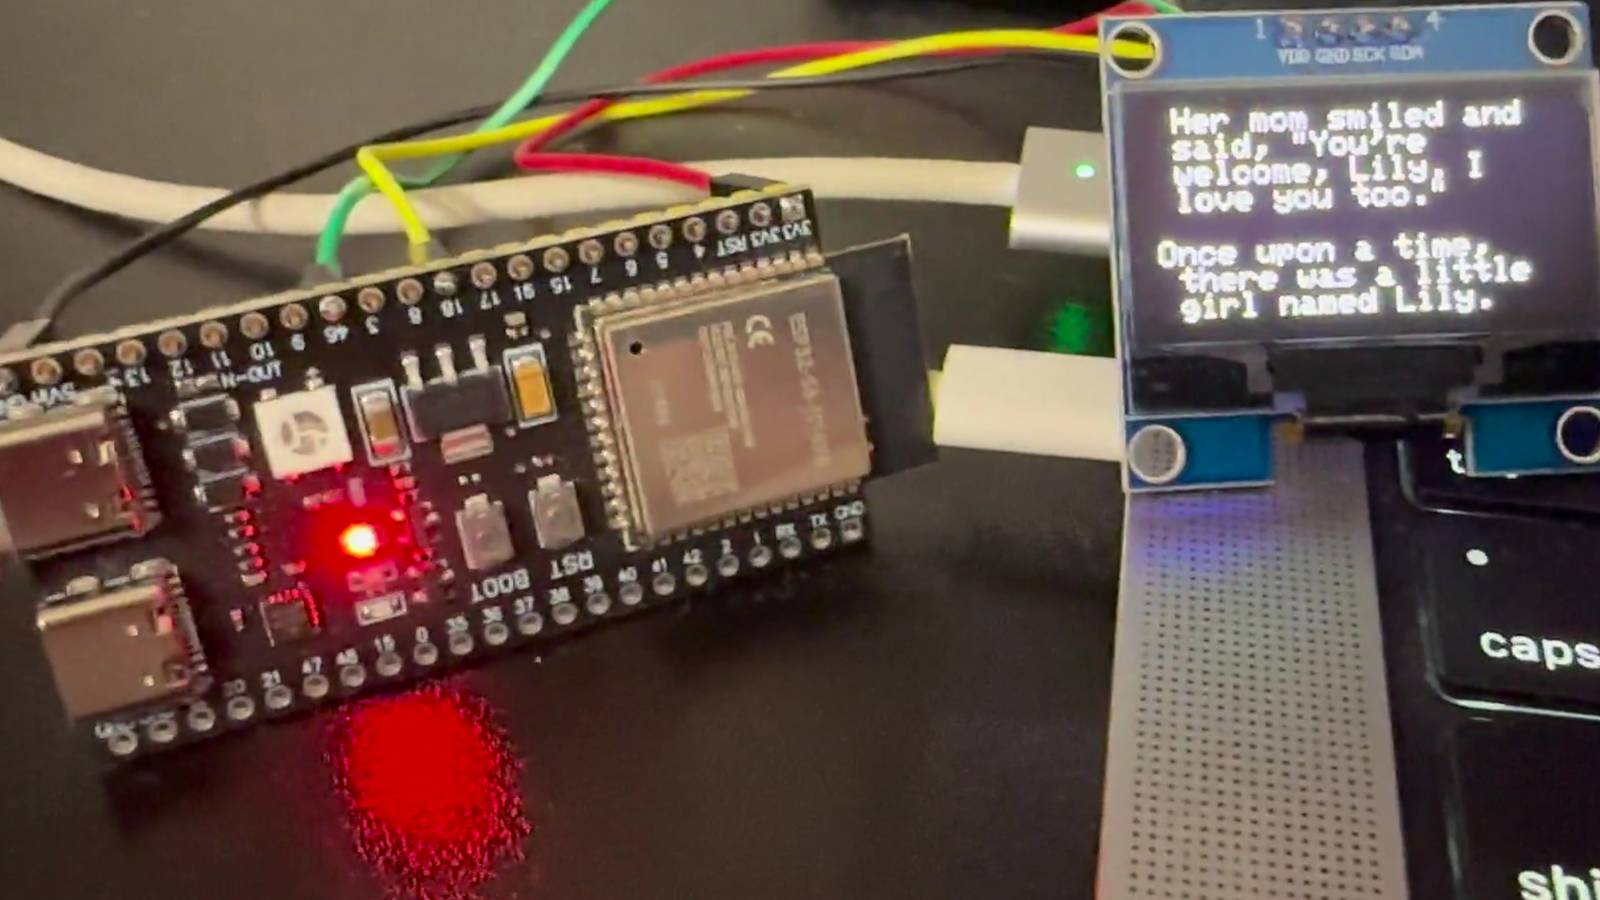
Someone squeezed a 28.9M LLM onto an ESP32-S3, and so can you: It can tell a mean story.
xda-developers.com/someone-squeezed-a-289m-llm-onto-an-esp32-s3-and-so-can-you/
Meta returns to open source with Muse Glimmer, an Apache 2.0 licensed 30B parameter LLM available now
venturebeat.com/technology/meta-returns-to-open-source-with-muse-glimmer-an-apache-2-0-licensed-30b-parameter-ai-model-optimized-for-agents-available-now
I tested every tiny local LLM worth running, and only three survived the cut: Small models are doing more than they should
xda-developers.com/tested-every-tiny-local-llm-worth-running-only-these-survived-the-cut/
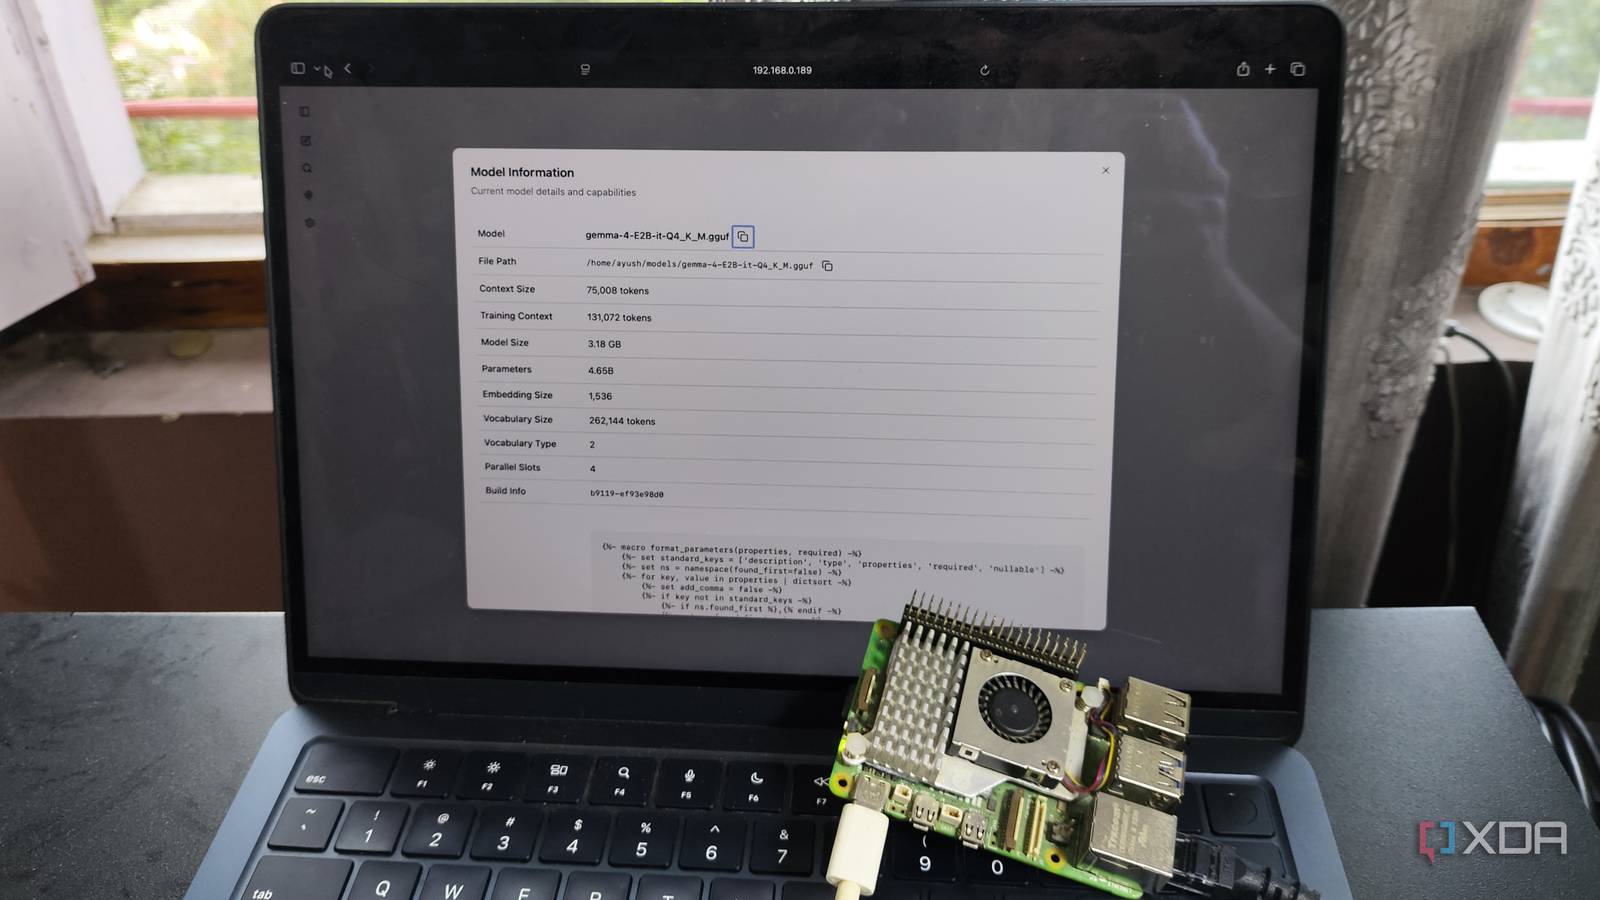
Gemma 4 E2B proves Raspberry Pi-sized LLMs don't have to be terrible anymore: It's a decently powerful LLM for something that can fit in a mere Raspberry Pi
xda-developers.com/gemma-4-e2b-proves-raspberry-pi-llms-dont-have-to-be-terrible/
github.com Aug 03
GitHub - nathanlgabriel/local_LLM_transitive_inf_assessment: Testing a few local models on their ability to debug and expand on poorly written model code from ...
github.com/nathanlgabriel/local_LLM_transitive_inf_assessment


dlvr.it Jul 27
Impostor Chinese models pretend they're Claude: Researchers find GLM and Kimi can adopt Claude's identity, but the evidence stops short of proving distillation
theregister.com/ai-and-ml/2026/07/27/impostor-chinese-models-pretend-theyre-claude/5279165
github.com Jul 30
GitHub - drumih/turbo-fieldfare: Gemma 4 26B-A4B inference in ~2 GB of RAM on any M-series MacBook
github.com/drumih/turbo-fieldfare

github.com Jul 31
GitHub - jscott3201/hyperion: M5-first local Gemma 4 inference in Rust + MLX.: M5-first local Gemma 4 inference in Rust + MLX. Contribute to jscott3201/hyperion ...
github.com/jscott3201/hyperion

Someone squeezed a 28.9M LLM onto an ESP32-S3, and so can you: It can tell a mean story.
xda-developers.com/someone-squeezed-a-289m-llm-onto-an-esp32-s3-and-so-can-you/

AI developer runs 28.9-million-parameter model on $10 ESP32-S3 microcontroller — uses Google's Per-Layer Embeddings technique ...
tomshardware.com/tech-industry/artificial-intelligence/ai-developer-runs-28-9-million-parameter-model-on-usd10-esp32-s3-microcontroller-uses-googles-per-layer-embeddings-technique-stores-table-on-16mb-flash-memory

Someone squeezed a 28.9M LLM onto an ESP32-S3, and so can you: It can tell a mean story.
xda-developers.com/someone-squeezed-a-289m-llm-onto-an-esp32-s3-and-so-can-you/

Small Language Models Power Life-Saving Small AI: In places with unreliable networks and no data-center infrastructure, smaller is better
spectrum.ieee.org/small-language-models-ai-pharmaceuticals

NASA Uses AI to Analyze Satellite Images in Orbit: Gemma 3 runs on Nvidia hardware to analyze satellite images
spectrum.ieee.org/nasa-ai-satellite-image-analysis
9to5google.com Jul 14
Google announces Gemma 4 optimized for the Pixel 10’s TPU: Google today announced Gemma 4 E2B for TPU that’s designed to run natively on the Pixel 10’s TPU ...
9to5google.com/2026/07/14/pixel-10-gemma-4/

Gemma 4 sees, hears, and reads on my 16GB laptop, and it never phones home: This model is the jack of all trades when it comes to local LLMs
xda-developers.com/gemma-4-sees-hears-and-reads-on-my-16gb-laptop-and-it-never-phones-home/
github.com Jul 16
GitHub - jegly/Box: The most advanced, fully offline client-side AI suite on Android today.
github.com/jegly/Box

Local LLMs finally beat cloud AI for coding, automation, and brainstorming — here's which ones I use
xda-developers.com/local-llms-finally-beat-cloud-ai-for-coding-automation-and-brainstorming-heres-which-ones-i-use/

Google’s latest Pixel AI push keeps your data on your phone: Google is bringing smarter Pixel experiences offline with Gemma 4, letting apps run faster and work ...
androidauthority.com/google-gemma-4-e2b-for-tpu-unveiled-3687531/
Small Language Models Power Life-Saving Small AI: In places with unreliable networks and no data-center infrastructure, smaller is better
spectrum.ieee.org/small-language-models-ai-pharmaceuticals
Key FactsSmall AI Transforms Healthcare in Resource-Limited Areas
Jul 7, 2026 · Reading time: ~45 sec.
Summary created with AI assistance · Source: spectrum.ieee.org
Summary created with AI assistance · Source: spectrum.ieee.org
- The RxScanner uses a compact AI model to authenticate drugs locally on phones without needing internet access.
- Small AI runs efficiently on affordable hardware like Arduino devices and smartphones equipped with neural processing units.
- Global initiatives, including from the World Bank, promote small AI deployment to improve health and agriculture in developing regions.
- Sustainable infrastructure and periodic updates remain essential for small AI solutions to maintain effectiveness over time.
If someone is not subsidizing it, most people will not be able to afford those models. So those of us who are said to be small-AI developers are the ones who will have to build for the majority of the world,— Adebayo Alonge, discussing why small-AI models must be subsidized to be affordable worldwide
I tried replacing my phone's cloud AI with a local model for a week, and here's what I gave up
xda-developers.com/tried-replacing-cloud-ai-with-local-model-what-i-gave-up/
I replaced Gemma 4 with a two-year-old coding LLM, and my local AI setup works better than ever
xda-developers.com/replaced-gemma-4-with-two-year-old-coding-llm-for-non-coding-work/
I stopped running the biggest local LLM that could fit, and a 2B model handles 90% of what I need
xda-developers.com/stopped-running-biggest-local-llm-that-could-fit-2b-model-handles-90-percent-what-i-need/
I almost upgraded my GPU to run larger local LLMs, but this 8B model proved I didn't have to
xda-developers.com/almost-upgraded-gpu-to-run-larger-local-llms-but-8b-model-proved-i-didnt-have-to/
github.com Jul 04
GitHub - jscott3201/Helios: Contribute to jscott3201/Helios development by creating an account on GitHub.
github.com/jscott3201/Helios

github.com Jul 04
Gemma4 layer scalar fix by kallewoof · Pull Request #4 · dnhkng/RYS: Contribute to dnhkng/RYS development by creating an account on GitHub.
github.com/dnhkng/RYS/pull/4

Gemma 4's smallest model runs on 3GB of VRAM, and it's the one I actually reach for
xda-developers.com/gemma-4-smallest-model-runs-on-3gb-vram-its-the-one-i-actually-reach-for/
Liquid AI's smallest model yet LFM2.5-230M beats models 4X its size at data extraction, can run 'anywhere'
venturebeat.com/technology/liquid-ais-smallest-model-yet-lfm2-5-230m-beats-models-4x-its-size-at-data-extraction-can-run-anywhere
I wanted Google’s secret AI dictation app to replace Wispr Flow, but it couldn’t: Google's AI Edge Eloquent offers free offline voice dictation ...
androidauthority.com/google-ai-edge-eloquent-vs-wispr-flow-3678620/
I tested 3 local LLMs for UI design work, and only one of them behaved like a real designer
xda-developers.com/tested-local-llms-for-ui-design-work-only-one-behaved-like-real-designer/
I tested Google's new Gemma 4 12B on my 8GB GPU, and now I don't want to go back to smaller models
xda-developers.com/tested-google-gemma-4-12b-on-8gb-gpu-and-dont-want-to-go-back-to-smaller-models/
I used Meta Llama 4, Qwen 3-Coder and Gemma 4 to develop a Python app, and only one model is worth keeping for developers
xda-developers.com/i-used-meta-llama-4-qwen-3-and-gemma-4-to-develop-a-python-app-and-only-one-model-is-worth-keeping-for-developers/
Google's DiffusionGemma runs text 4x faster: Google's open-source diffusion language model generates 256 tokens in parallel and self-corrects ...
venturebeat.com/technology/googles-diffusiongemma-generates-256-tokens-in-parallel-and-self-corrects-as-it-goes
I solved Gemma 4's biggest problem by routing it through Claude, and all it took was a Python script
xda-developers.com/i-solved-gemma-4s-biggest-problem-by-asking-it-to-call-claude-and-all-it-took-was-a-python-script/
I tested 3 tiny local LLMs for everyday work, and only one of them impressed me: Small but not useless
xda-developers.com/tested-tiny-local-llms-for-everyday-work-only-one-impressed-me/
github.com Jun 21
GitHub - mikechambers84/ik_llama.cpp at numa-mirror: ik_llama.cpp fork with experimental NUMA per-node mirroring of model weights and KV cache ...
github.com/mikechambers84/ik_llama.cpp/tree/numa-mirror
I tested my local LLM across 4 different tools, and only one actually unleashed its potential
xda-developers.com/tested-local-llm-different-tools-and-only-one-unleashed-its-potential/

Google's free Gemma 4 model runs on hardware you probably already own: This surprisingly powerful model runs on a proverbial toaster
xda-developers.com/googles-free-gemma-4-model-runs-on-hardware-you-probably-already-own/
I ran Gemma, Llama, and Qwen on my phone, and only one of them is worth the storage
xda-developers.com/ran-gemma-llama-qwen-on-phone-only-one-is-worth-the-storage/

A satellite just learned to find things on its own — here’s what that means: In April, for the first time ever, an Earth observation satellite found what it was ...
techcrunch.com/2026/06/15/a-satellite-just-learned-to-find-things-on-its-own-heres-what-that-means/

I replaced ChatGPT, Claude, and Gemini on my phone with a local LLM, and it's a mobile upgrade I didn't expect
xda-developers.com/replaced-chatgpt-claude-gemini-on-phone-with-local-llm/
I tested 3 tiny local LLMs for everyday work, and only one of them impressed me: Small but not useless
xda-developers.com/tested-tiny-local-llms-for-everyday-work-only-one-impressed-me/
Google's free Gemma 4 model runs on hardware you probably already own: This surprisingly powerful model runs on a proverbial toaster
xda-developers.com/googles-free-gemma-4-model-runs-on-hardware-you-probably-already-own/

The New Stack Jun 05
Google Gemma 4 12B nearly matches 26B benchmarks — and runs on your laptop: Small enough to run locally on 16GB, the new addition to the Gemma model family with ...
thenewstack.io/google-gemma-local-ai/


Computerworld Jun 13
Google unveils DiffusionGemma, an AI model that breaks free of left-to-right processing
computerworld.com/article/4184675/google-unveils-diffusiongemma-an-ai-model-that-breaks-free-of-left-to-right-processing-2.html


Ziff Davis Jun 08
Google Challenges Apple’s AI Missteps With Local Gemma AI for Mac: The app is now available for Macs with Apple Silicon chips and macOS 14 or later.
extremetech.com/computing/google-challenges-apples-ai-missteps-with-local-gemma-ai-for-mac

github.com Jun 08
club-3090/models/qwen3.6-27b/vllm/compose/dual/fp8/mtp.yml at master · noonghunna/club-3090
github.com/noonghunna/club-3090/blob/master/models/qwen3.6-27b/vllm/compose/dual/fp8/mtp.yml


9to5Mac Jun 04
Google AI Edge Gallery launches on macOS, letting Mac users run Gemini models locally
9to5mac.com/2026/06/03/google-ai-edge-gallery-launches-to-macos-letting-mac-users-run-gemini-models-locally/

Google’s latest on-device AI model is custom-made for your laptop: Google has released the Gemma 4 12B multimodal agentic AI model that's designed to run on ...
androidauthority.com/google-gemma-4-12b-multimodal-ai-model-3674379/
I finally found an open-source local LLM that actually competes with cloud AI: Open-source is catching up
xda-developers.com/found-open-source-local-llm-that-competes-with-cloud-ai-gemma-4/
github.com Jun 02
club-3090/models/qwen3.6-27b/vllm/compose/dual/carnice-bf16mtp/bf16-mtp.yml at master · noonghunna/club-3090
github.com/noonghunna/club-3090/blob/master/models/qwen3.6-27b/vllm/compose/dual/carnice-bf16mtp/bf16-mtp.yml

I tested 3 tiny local LLMs for everyday work, and only one of them impressed me: Small but not useless
xda-developers.com/tested-tiny-local-llms-for-everyday-work-only-one-impressed-me/
I ditched LM Studio for llama.cpp, and my local LLM doesn't feel like a downgrade anymore
xda-developers.com/ditched-lm-studio-for-llama-cpp-and-local-llm-doesnt-feel-like-downgrade-anymore/
github.com May 29
GitHub - unslothai/unsloth: Unsloth Studio is a web UI for training and running open models like Gemma 4, Qwen3.6, DeepSeek, gpt-oss locally.
github.com/unslothai/unsloth

github.com May 20
llama : add Gemma4 MTP by am17an · Pull Request #23398 · ggml-org/llama.cpp: LLM inference in C/C++. Contribute to ggml-org/llama.cpp development by creating an ...
github.com/ggml-org/llama.cpp/pull/23398

I finally found an open-source local LLM that actually competes with cloud AI: Open-source is catching up
xda-developers.com/found-open-source-local-llm-that-competes-with-cloud-ai-gemma-4/