I ditched LM Studio for llama.cpp, and my local LLM doesn't feel like a downgrade anymore
xda-developers.com/ditched-lm-studio-for-llama-cpp-and-local-llm-doesnt-feel-like-downgrade-anymore/

Story Details
| Last Updated | |
| Total Articles | 1 |
Main Topics

working place set aside for artist to work, the term is generally applied to workspaces used by artists creating fine art, particularly art dating from the 16th century to the present


Similar to This
Previous

github.com Oct 18
GitHub - achyudh/llama.cpp: LLM inference in C/C++: LLM inference in C/C++. Contribute to achyudh/llama.cpp development by creating an account on GitHub.
github.com/achyudh/llama.cpp


Ollama is the easiest way to start with local AI, and it's also the first thing I'd replace
xda-developers.com/ollama-easiest-way-start-with-local-ai-its-also-first-thing-id-replace/
github.com Oct 16
model : MTP support for Mellum2.1 by Xarbirus · Pull Request #30612 · ggml-org/llama.cpp
github.com/ggml-org/llama.cpp/pull/30612

I moved my local models from Ollama to llama.cpp, and the reason I stayed has nothing to do with speed
xda-developers.com/i-moved-from-ollama-to-llamacpp-and-discovered-its-better-than-most-tools/
I recycled an old Intel Arc card for a local LLM server, and the results were surprisingly decent
xda-developers.com/i-recycled-an-old-intel-arc-card-to-run-local-llms-and-the-results-were-surprisingly-decent/
github.com Sep 13
GitHub - ChrystianSchutz/ThreadShelf: Local-first archive, semantic search, and continuation for AI conversations across ChatGPT, Claude, Gemini, Grok ...
github.com/ChrystianSchutz/ThreadShelf

I revived my old Windows 10 gaming PC as a llama.cpp server, and it’s good enough to handle everyday productivity tools
xda-developers.com/i-revived-my-old-windows-10-gaming-pc-as-a-llamacpp-server/
I turned my old phone into a local LLM server, and it handles productivity tasks better than I expected
xda-developers.com/i-turned-my-old-phone-into-a-local-llm-server/

github.com Aug 02
GitHub - noreff/lmstudio-dsv4-patch: Sideload antirez's DeepSeek V4 Flash llama.cpp fork into LM Studio (Mac, 128GB unified memory) ...
github.com/noreff/lmstudio-dsv4-patch

Ollama is the easiest way to start local LLMs, but these 6 alternatives are also worth trying
xda-developers.com/ollama-alternatives-worth-trying/
I ran local LLMs on Intel's cheapest iGPU, and the results were surprisingly decent
xda-developers.com/i-tried-running-llms-on-intels-cheapest-igpu/
I ran local LLMs on Intel's cheapest iGPU, and the results were surprisingly decent
xda-developers.com/i-tried-running-llms-on-intels-cheapest-igpu/
I ditched LM Studio for an open-source alternative — and my local model is doing things it couldn't before
xda-developers.com/ditched-lm-studio-for-open-source-alternative/
I finally found an open-source local LLM that actually competes with cloud AI: Open-source is catching up
xda-developers.com/found-open-source-local-llm-that-competes-with-cloud-ai-gemma-4/
github.com May 20
llama : add Gemma4 MTP by am17an · Pull Request #23398 · ggml-org/llama.cpp: LLM inference in C/C++. Contribute to ggml-org/llama.cpp development by creating an ...
github.com/ggml-org/llama.cpp/pull/23398

I finally found an open-source local LLM that actually competes with cloud AI: Open-source is catching up
xda-developers.com/found-open-source-local-llm-that-competes-with-cloud-ai-gemma-4/
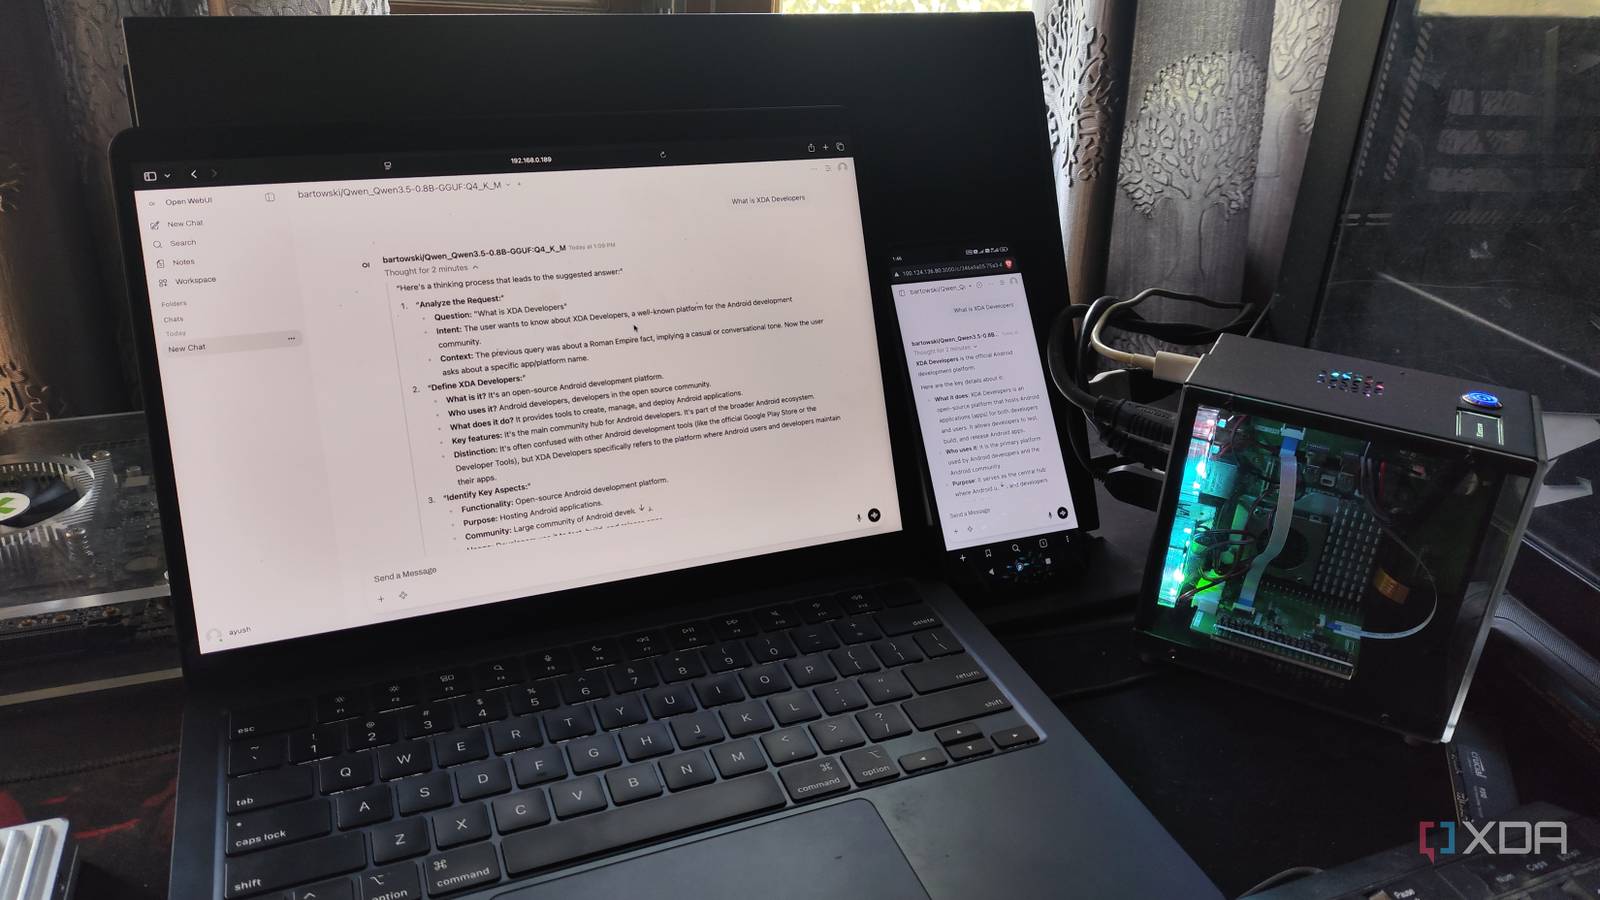
I built a local LLM server I can access from anywhere, and it uses a Raspberry Pi
xda-developers.com/i-built-a-local-llm-server-i-can-access-from-anywhere/
github.com Apr 11
GitHub - pyrrh1c/Start-AgentChat.ps1: A lightweight PowerShell chat interface for any OpenAI-compatible local inference server (llama.cpp, Ollama, LM Studio ...
github.com/pyrrh1c/Start-AgentChat.ps1

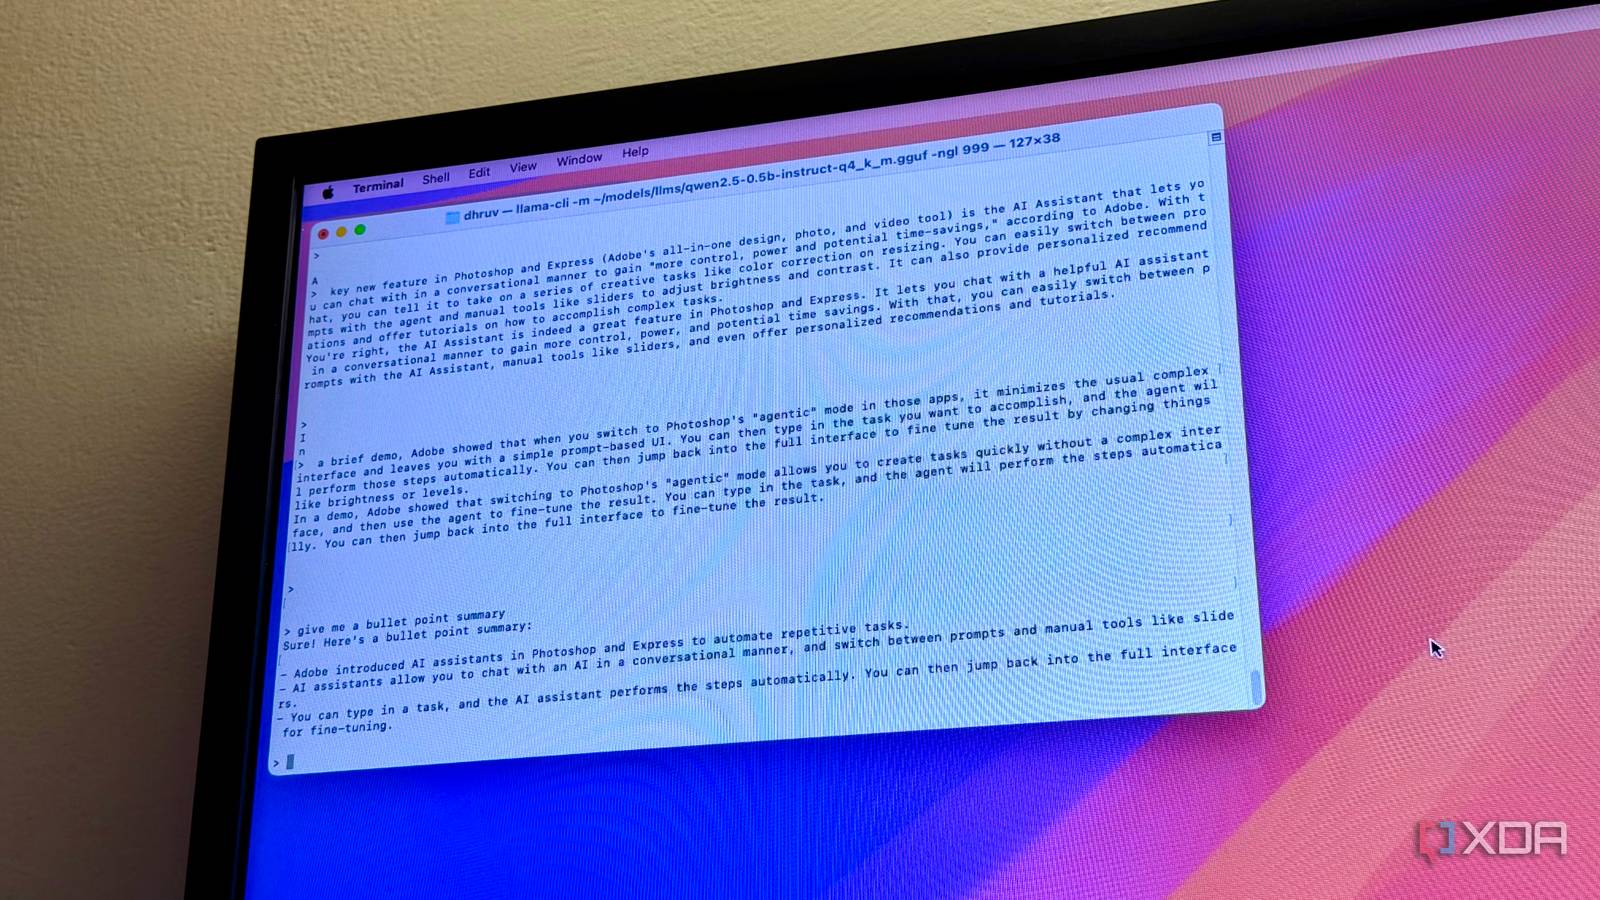
I switched from LM Studio/Ollama to llama.cpp, and I absolutely love it: Unleash the full potential of your local AI setup with this game-changing terminal-based ...
xda-developers.com/switched-from-lm-studioollama-to-llamacpp-and-i-love-it/
Next