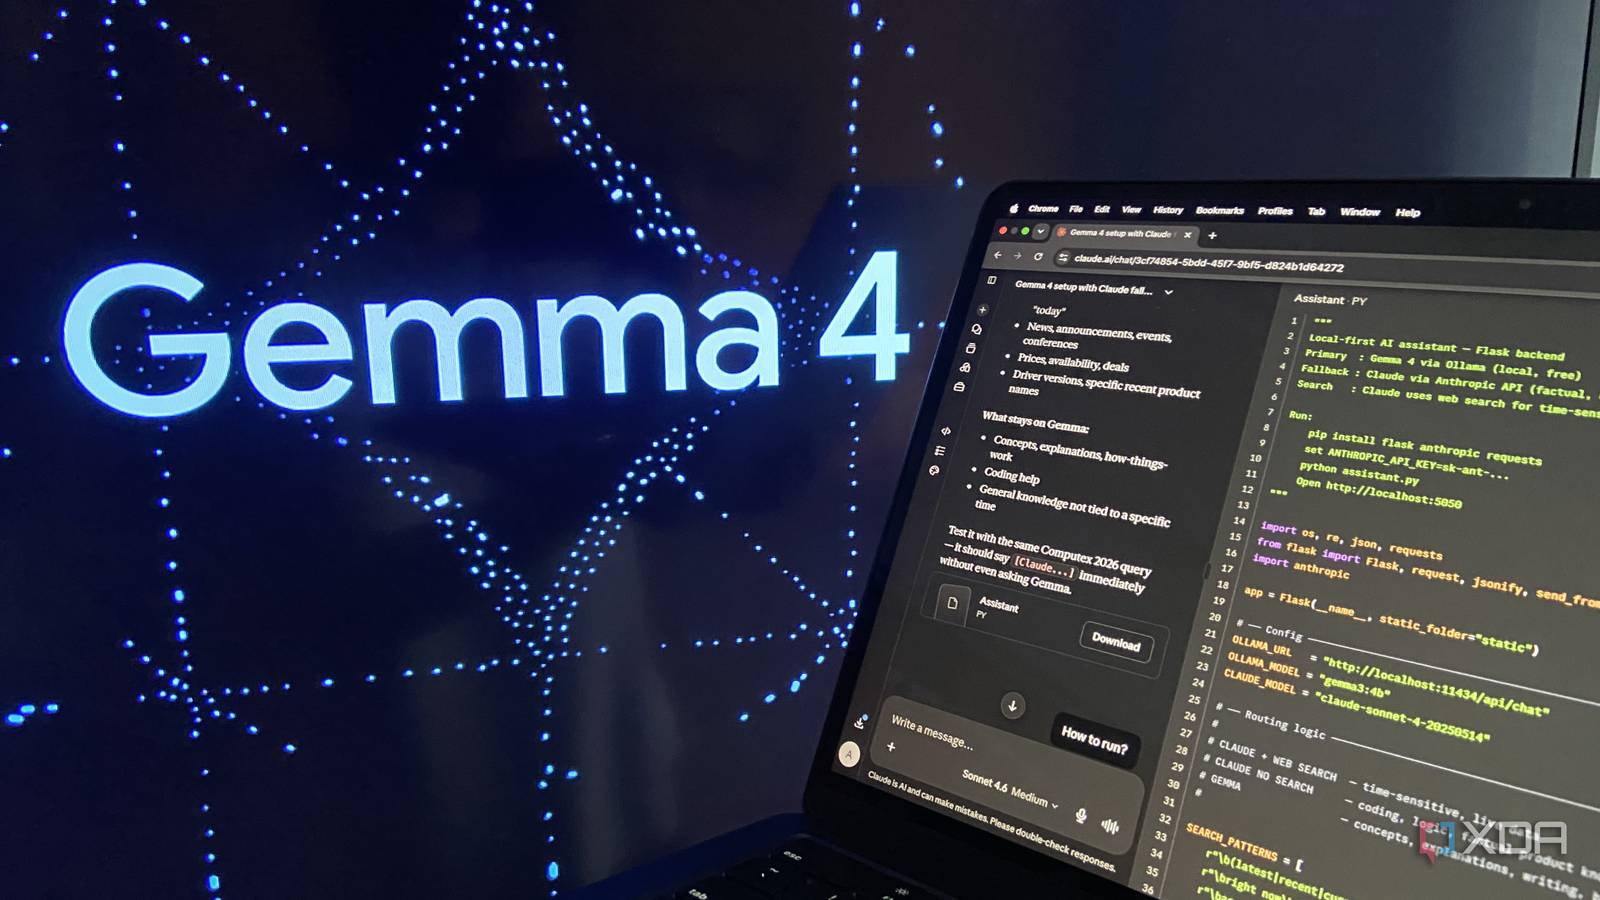
I solved Gemma 4's biggest problem by routing it through Claude, and all it took was a Python script
xda-developers.com/i-solved-gemma-4s-biggest-problem-by-asking-it-to-call-claude-and-all-it-took-was-a-python-script/
Story Details
| Last Updated | |
| Total Articles | 1 |
Main Topics


More articles on this subject
Previous

I solved Gemma 4's biggest problem by routing it through Claude, and all it took was a Python script
xda-developers.com/i-solved-gemma-4s-biggest-problem-by-asking-it-to-call-claude-and-all-it-took-was-a-python-script/
Next
Similar to This
Previous
My local LLM is small enough to run on my laptop, but smart enough to replace these 3 subscriptions
xda-developers.com/my-local-llm-is-small-enough-to-run-on-my-laptop-but-smart-enough-to-replace-these-x-subscriptions/

After trying 20+ local LLMs, these are the 4 I keep installed for different jobs: My local AI setup isn’t about collecting models, it’s about having the right ...
xda-developers.com/local-llms-i-keep-installed-for-different-jobs/

No cloud, no GPUs, no problem: Liquid AI's new model LFM2.5-2.6B brings powerful AI agents to devices as small as a Raspberry Pi
venturebeat.com/technology/no-cloud-no-gpus-no-problem-liquid-ais-new-model-lfm2-5-2-6b-brings-powerful-ai-agents-to-devices-as-small-as-a-raspberry-pi
I tested every tiny local LLM worth running, and only three survived the cut: Small models are doing more than they should
xda-developers.com/tested-every-tiny-local-llm-worth-running-only-these-survived-the-cut/

github.com Jul 31
GitHub - jscott3201/hyperion: M5-first local Gemma 4 inference in Rust + MLX.: M5-first local Gemma 4 inference in Rust + MLX. Contribute to jscott3201/hyperion ...
github.com/jscott3201/hyperion


dlvr.it Jul 27
Impostor Chinese models pretend they're Claude: Researchers find GLM and Kimi can adopt Claude's identity, but the evidence stops short of proving distillation
theregister.com/ai-and-ml/2026/07/27/impostor-chinese-models-pretend-theyre-claude/5279165
Local LLMs finally beat cloud AI for coding, automation, and brainstorming — here's which ones I use
xda-developers.com/local-llms-finally-beat-cloud-ai-for-coding-automation-and-brainstorming-heres-which-ones-i-use/
Your phone + a $0 local model beats paying for Claude Pro, and here's what I actually do with it
xda-developers.com/your-phone-plus-a-home-hosted-local-llm-beats-claude-pro/
I replaced Gemma 4 with a two-year-old coding LLM, and my local AI setup works better than ever
xda-developers.com/replaced-gemma-4-with-two-year-old-coding-llm-for-non-coding-work/
I stopped running the biggest local LLM that could fit, and a 2B model handles 90% of what I need
xda-developers.com/stopped-running-biggest-local-llm-that-could-fit-2b-model-handles-90-percent-what-i-need/
I used Meta Llama 4, Qwen 3-Coder and Gemma 4 to develop a Python app, and only one model is worth keeping for developers
xda-developers.com/i-used-meta-llama-4-qwen-3-and-gemma-4-to-develop-a-python-app-and-only-one-model-is-worth-keeping-for-developers/
I almost upgraded my GPU to run larger local LLMs, but this 8B model proved I didn't have to
xda-developers.com/almost-upgraded-gpu-to-run-larger-local-llms-but-8b-model-proved-i-didnt-have-to/
Liquid AI's smallest model yet LFM2.5-230M beats models 4X its size at data extraction, can run 'anywhere'
venturebeat.com/technology/liquid-ais-smallest-model-yet-lfm2-5-230m-beats-models-4x-its-size-at-data-extraction-can-run-anywhere
I replaced ChatGPT, Claude, and Gemini on my phone with a local LLM, and it's a mobile upgrade I didn't expect
xda-developers.com/replaced-chatgpt-claude-gemini-on-phone-with-local-llm/
github.com Apr 15
GitHub - autocode-rayes/LLM-for-small-memory: Gemma 4 26B on 8GB VRAM — 25 tok/s on a 4060 mobile
github.com/autocode-rayes/LLM-for-small-memory

github.com Mar 16
GitHub - Andrew082904/gpupair: Contribute to Andrew082904/gpupair development by creating an account on GitHub.
github.com/Andrew082904/gpupair


Google TranslateGemma released in response to ChatGPT Translate: Here’s how it beats the OpenAI solution
financialexpress.com/life/technology-google-translategemma-released-in-response-to-chatgpt-translate-heres-how-it-beats-the-openai-solution-4109379/

Shedding light on AI's black box: The prospect of harnessing generative AI to make decisions is pushing researchers to better understand how AI systems work
axios.com/2024/08/22/ai-llms-black-box-interpretability-evaluation

What we know about Apple’s on-device AI: Apple's on-device AI uses optimization techniques and specialized hardware to strike the right balance between ...
venturebeat.com/ai/what-we-know-about-apples-on-device-ai/

Next