
github.com Sep 23
GitHub - W61k3r/LexiPanel: Self-hosted control panel for local AI on your own GPU box: run llama.cpp chat models, stable-diffusion.cpp images and audio ...
github.com/W61k3r/LexiPanel

Story Details
| Last Updated | |
| Total Articles | 1 |
Main Topics

specialized electronic circuit; graphics accelerator


software application for retrieving, presenting, and traversing information resources on the World Wide Web
Similar to This
Previous
github.com Oct 24
llama-on-legacy-gpu/README.md at main · theIvanR/llama-on-legacy-gpu: High performance llama cpp patches and fork for legacy gpus - llama-on-legacy-gpu/README ...
github.com/theIvanR/llama-on-legacy-gpu/blob/main/README.md

github.com Oct 18
GitHub - achyudh/llama.cpp: LLM inference in C/C++: LLM inference in C/C++. Contribute to achyudh/llama.cpp development by creating an account on GitHub.
github.com/achyudh/llama.cpp


Ollama is the easiest way to start with local AI, and it's also the first thing I'd replace
xda-developers.com/ollama-easiest-way-start-with-local-ai-its-also-first-thing-id-replace/
I moved my local models from Ollama to llama.cpp, and the reason I stayed has nothing to do with speed
xda-developers.com/i-moved-from-ollama-to-llamacpp-and-discovered-its-better-than-most-tools/
I ran GLM 5.3, a 744-billion-parameter model, on my home lab, and the frontier suddenly feels a lot closer
xda-developers.com/you-can-run-a-744b-model-on-your-own-hardware/
github.com Oct 03
GitHub - MohammadHaishemKhawaja/hashyy: A full, unpruned 177B MoE model at 11.5 tok/s on one 12 GB GPU. Expert streaming for llama.cpp ...
github.com/MohammadHaishemKhawaja/hashyy

My mini PC can fit larger models than my old gaming card, but it still loses on one key metric
xda-developers.com/my-mini-pc-can-fit-larger-models-than-my-old-gaming-card-but-it-still-loses-on-one-key-metric/
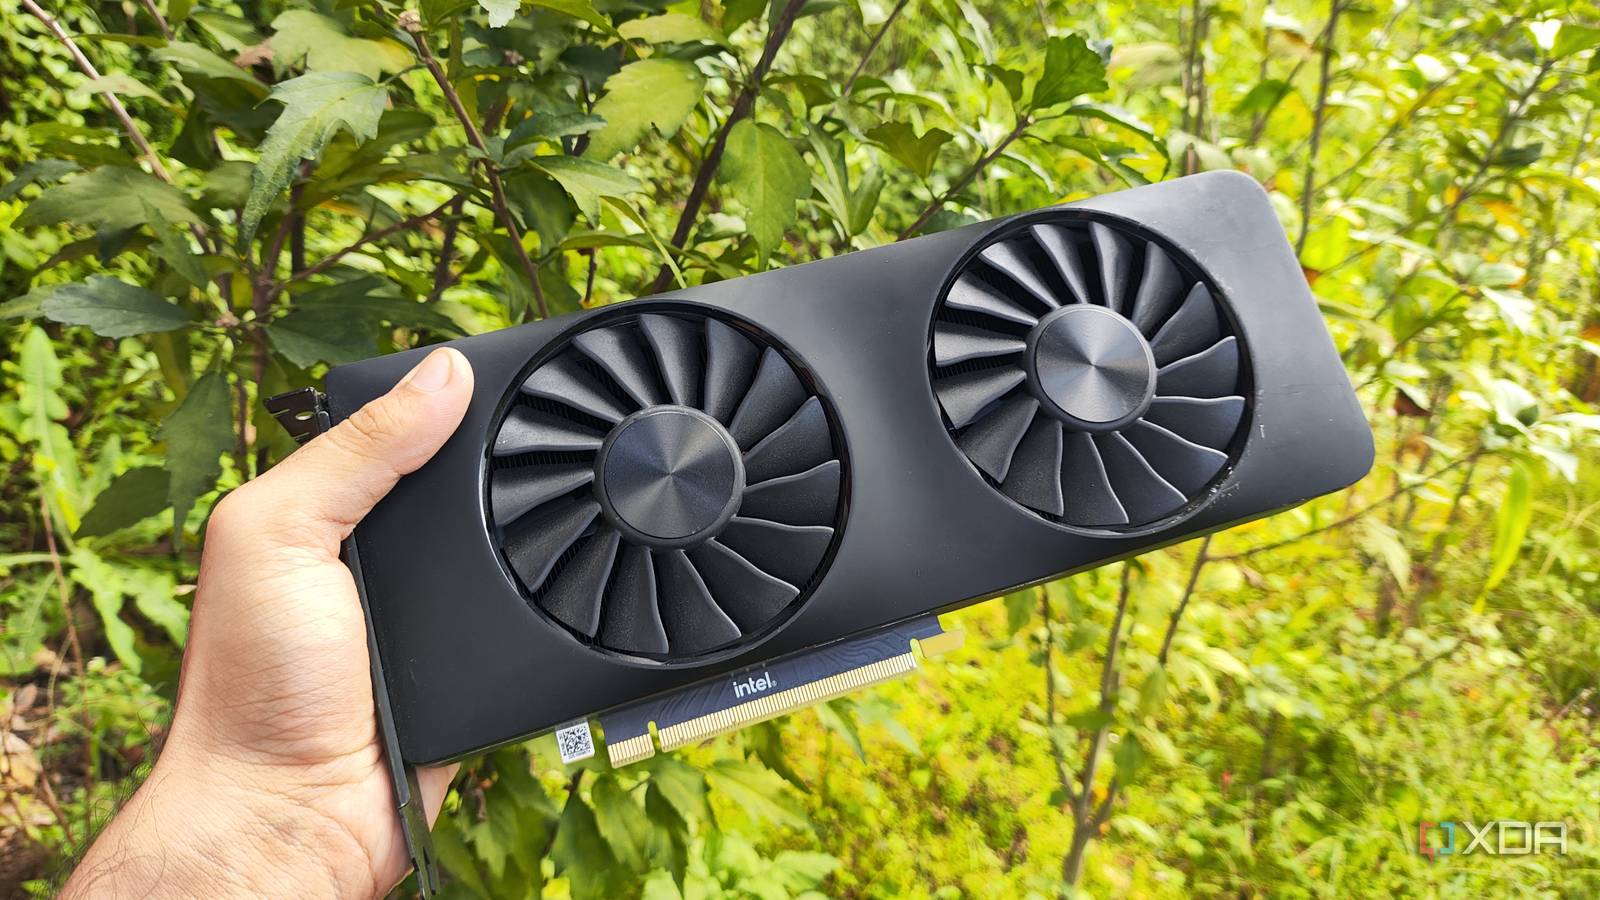
I recycled an old Intel Arc card for a local LLM server, and the results were surprisingly decent
xda-developers.com/i-recycled-an-old-intel-arc-card-to-run-local-llms-and-the-results-were-surprisingly-decent/
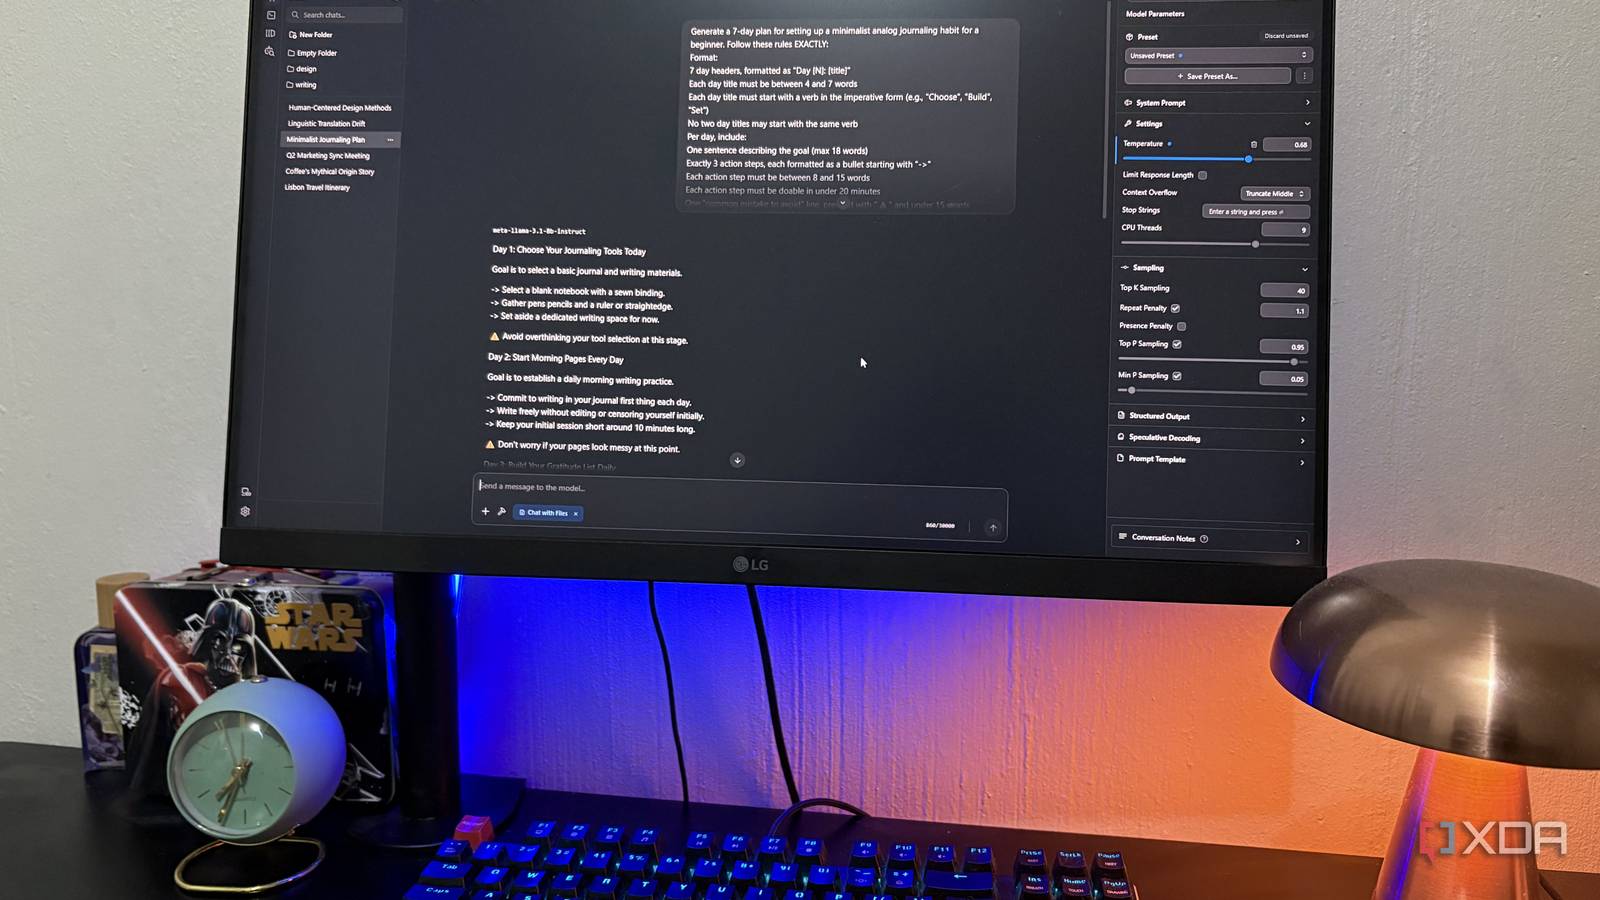
Ollama is the easiest way to start local LLMs, but these 6 alternatives are also worth trying
xda-developers.com/ollama-alternatives-worth-trying/
github.com Apr 15
GitHub - ParmesanParty/llama.cpp: Specialized fork for (relatively) fast single-GPU inference (in CUDA) using large MoE models that don't fit fully into ...
github.com/ParmesanParty/llama.cpp
github.com Mar 24
GitHub - thebeedubya/autoresearch: Running 397B parameter AI models on a $2500 Strix Halo desktop. 128GB UMA, no cloud, no datacenter.
github.com/thebeedubya/autoresearch

github.com Mar 14
Release b8338 · ggml-org/llama.cpp: LLM inference in C/C++. Contribute to ggml-org/llama.cpp development by creating an account on GitHub.
github.com/ggml-org/llama.cpp/releases/tag/b8338
github.com Mar 11
GitHub - raketenkater/llm-server: Smart launcher for llama.cpp / ik_llama.cpp — auto-detects GPUs, optimizes MoE placement, crash recovery
github.com/raketenkater/llm-server

github.com Feb 20
GitHub - peva3/SmarterRouter: SmarterRouter: An intelligent LLM gateway and VRAM-aware router for Ollama, llama.cpp, and OpenAI. Features semantic caching ...
github.com/peva3/SmarterRouter

Next