
github.com Mar 11
GitHub - raketenkater/llm-server: Smart launcher for llama.cpp / ik_llama.cpp — auto-detects GPUs, optimizes MoE placement, crash recovery
github.com/raketenkater/llm-server

Story Details
| Last Updated | |
| Total Articles | 1 |
Main Topics


specialized electronic circuit; graphics accelerator
Similar to This
Previous
github.com 10h
llama-on-legacy-gpu/README.md at main · theIvanR/llama-on-legacy-gpu: High performance llama cpp patches and fork for legacy gpus - llama-on-legacy-gpu/README ...
github.com/theIvanR/llama-on-legacy-gpu/blob/main/README.md


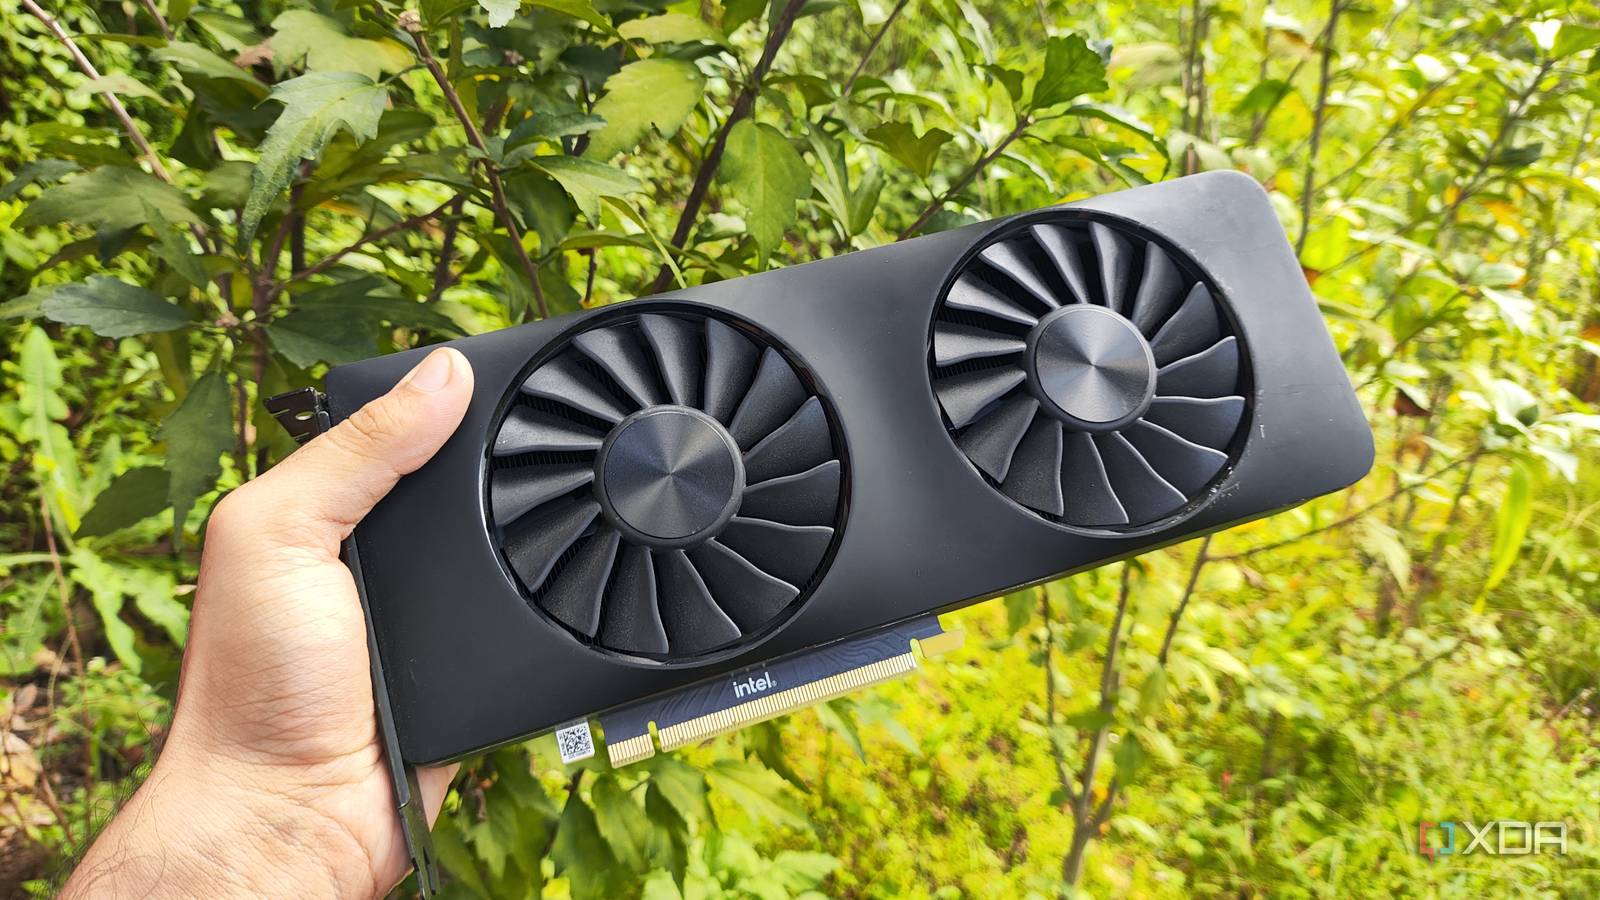
I recycled an old Intel Arc card for a local LLM server, and the results were surprisingly decent
xda-developers.com/i-recycled-an-old-intel-arc-card-to-run-local-llms-and-the-results-were-surprisingly-decent/
github.com Sep 20
GitHub - edwardyoon/focus-llama: A llama.cpp fork for Dynamic Attention Masking: A llama.cpp fork for Dynamic Attention Masking. Contribute to ...
github.com/edwardyoon/focus-llama

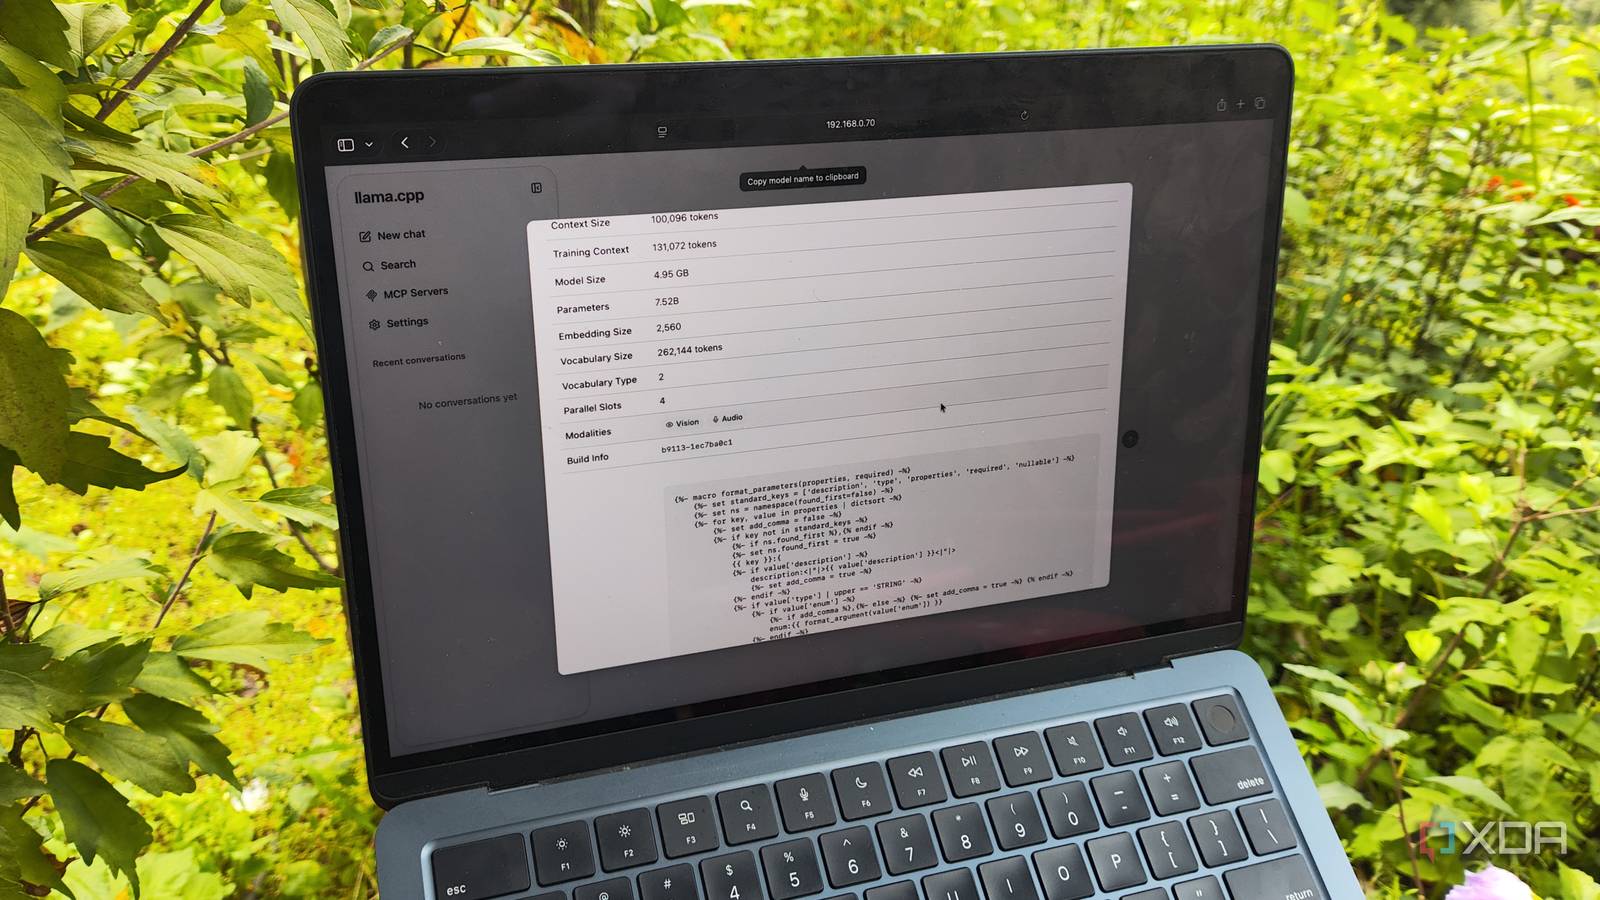
I revived my old Windows 10 gaming PC as a llama.cpp server, and it’s good enough to handle everyday productivity tools
xda-developers.com/i-revived-my-old-windows-10-gaming-pc-as-a-llamacpp-server/
github.com Aug 27
GitHub - ccebelenski/localagents: MCP server that delegates Claude Code agent work to local models (llama.cpp / vLLM) on your own hardware
github.com/ccebelenski/localagents

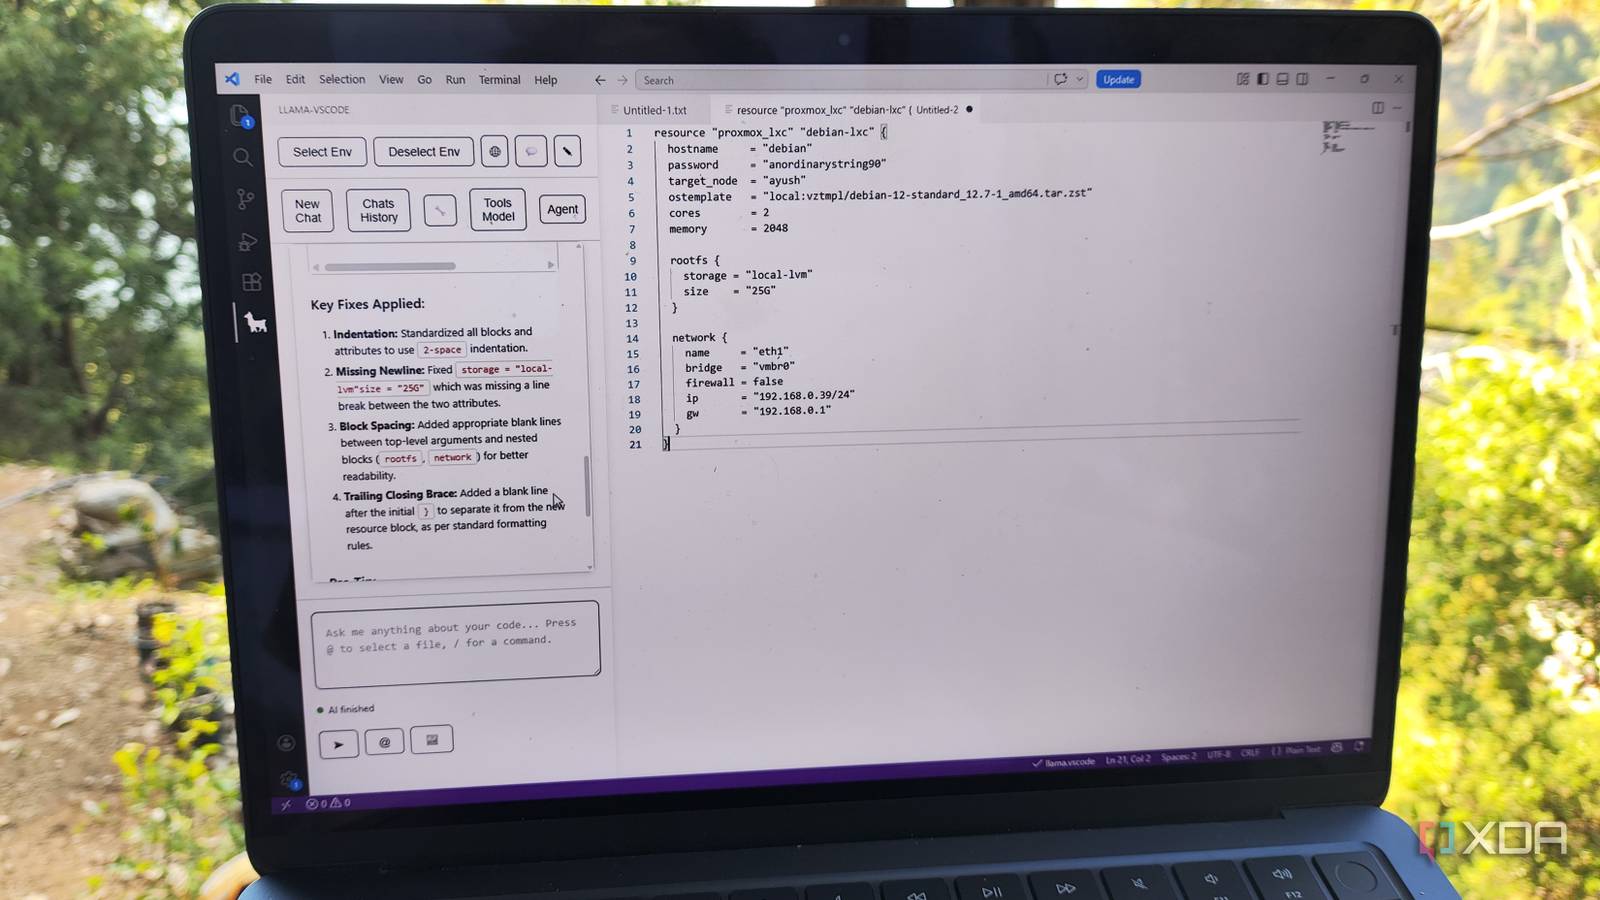
Two old GPUs I salvaged are doing more AI work than a brand new $2000 card, and I won't be upgrading anytime soon
xda-developers.com/two-old-gpus-are-doing-more-ai-work-than-a-brand-new-card/
Two old GPUs I salvaged are doing more AI work than a brand new $2000 card, and I won't be upgrading anytime soon
xda-developers.com/two-old-gpus-are-doing-more-ai-work-than-a-brand-new-card/
Two old GPUs I salvaged are doing more AI work than a brand new $2000 card, and I won't be upgrading anytime soon
xda-developers.com/two-old-gpus-are-doing-more-ai-work-than-a-brand-new-card/
Two old GPUs I salvaged are doing more AI work than a brand new $2000 card, and I won't be upgrading anytime soon
xda-developers.com/two-old-gpus-are-doing-more-ai-work-than-a-brand-new-card/
Two old GPUs I salvaged are doing more AI work than a brand new $2000 card, and I won't be upgrading anytime soon
xda-developers.com/two-old-gpus-are-doing-more-ai-work-than-a-brand-new-card/
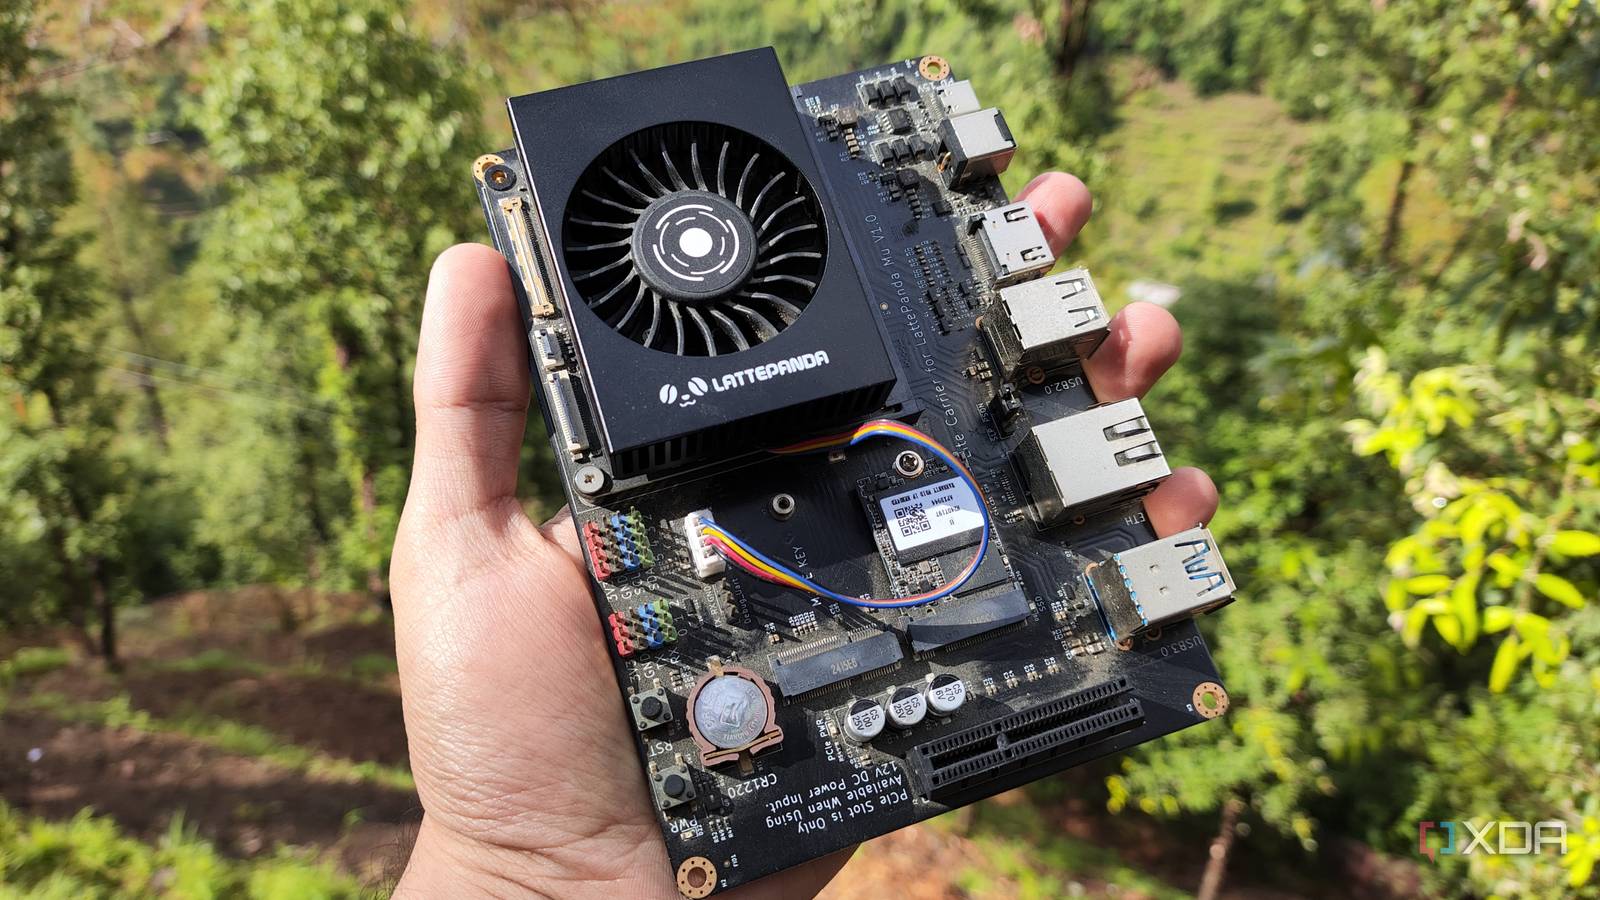
I ran local LLMs on Intel's cheapest iGPU, and the results were surprisingly decent
xda-developers.com/i-tried-running-llms-on-intels-cheapest-igpu/
I ran local LLMs on Intel's cheapest iGPU, and the results were surprisingly decent
xda-developers.com/i-tried-running-llms-on-intels-cheapest-igpu/
github.com May 21
server: fix checkpoints creation by jacekpoplawski · Pull Request #22929 · ggml-org/llama.cpp
github.com/ggml-org/llama.cpp/pull/22929

github.com Apr 14
GitHub - ag88/llama.cpp-model-runner: runmodel.sh a simple model launcher for llama.cpp / llama-server
github.com/ag88/llama.cpp-model-runner

github.com Apr 05
GitHub - Sakatard/llm-inference-server: Unified GPU inference server: Qwen 3.5 + Whisper + TimesFM 2.5 on Tesla P40
github.com/Sakatard/llm-inference-server

github.com Feb 20
GitHub - peva3/SmarterRouter: SmarterRouter: An intelligent LLM gateway and VRAM-aware router for Ollama, llama.cpp, and OpenAI. Features semantic caching ...
github.com/peva3/SmarterRouter

Next