
trendforce Jul 31
💡 Memory Is Buckling Under KV Cache Demand, Two Fixes Are in Play. Surging KV Cache demand against constrained memory supply created severe bottlenecks ... Show more
Story Details
| Last Updated | |
| Total Articles | 1 |
Main Topics

computing component that transparently stores data so that future requests for that data can be served faster


Similar to This
Previous

How flash storage can cut GPU waste from KV-cache recomputation: LLM inference can waste up to 60% of GPU compute recomputing context. WEKA explains how KV-cache ...
venturebeat.com/ai/up-to-60-of-gpu-compute-goes-to-recomputing-context-flash-storage-can-put-that-capacity-back-to-work

github.com Sep 28
GitHub - solvingSteve/Gevva0: System 0 local decision gateway powered by Gemma 4. Direct logit scoring, KV-cache sequence branching ...
github.com/solvingSteve/Gevva0

C2C replaces text handoffs between AI models | VentureBeat: C2C lets AI models communicate through KV caches instead of text, improving benchmark accuracy and ...
venturebeat.com/orchestration/text-handoffs-slow-ai-models-down-c2c-lets-them-communicate-through-kv-caches-instead

Marvell VP pushes for DDR4 recycling for use in CXL memory, amid the worst DRAM shortage in years — company introduces three-tier AI memory infrastructure
tomshardware.com/pc-components/dram/marvell-sells-cxl-memory-recycling-into-the-worst-dram-shortage-in-years
 Paid articlePaywall

A requiem for Optane, Intel's KV cache killer that could have eased the RAM price crunch
theregister.com/storage/2026/07/29/a-requiem-for-optane-intels-kv-cache-killer-that-could-have-eased-the-ram-price-crunch/5280063

trendforce Jul 30
Breaking the Memory Bottleneck Part 2: How Tech Giants Shrink the KV Cache Footprint
insights.trendforce.com/p/memory-bottleneck-shrinking-kv-cache-footprint
 Paid articlePaywall
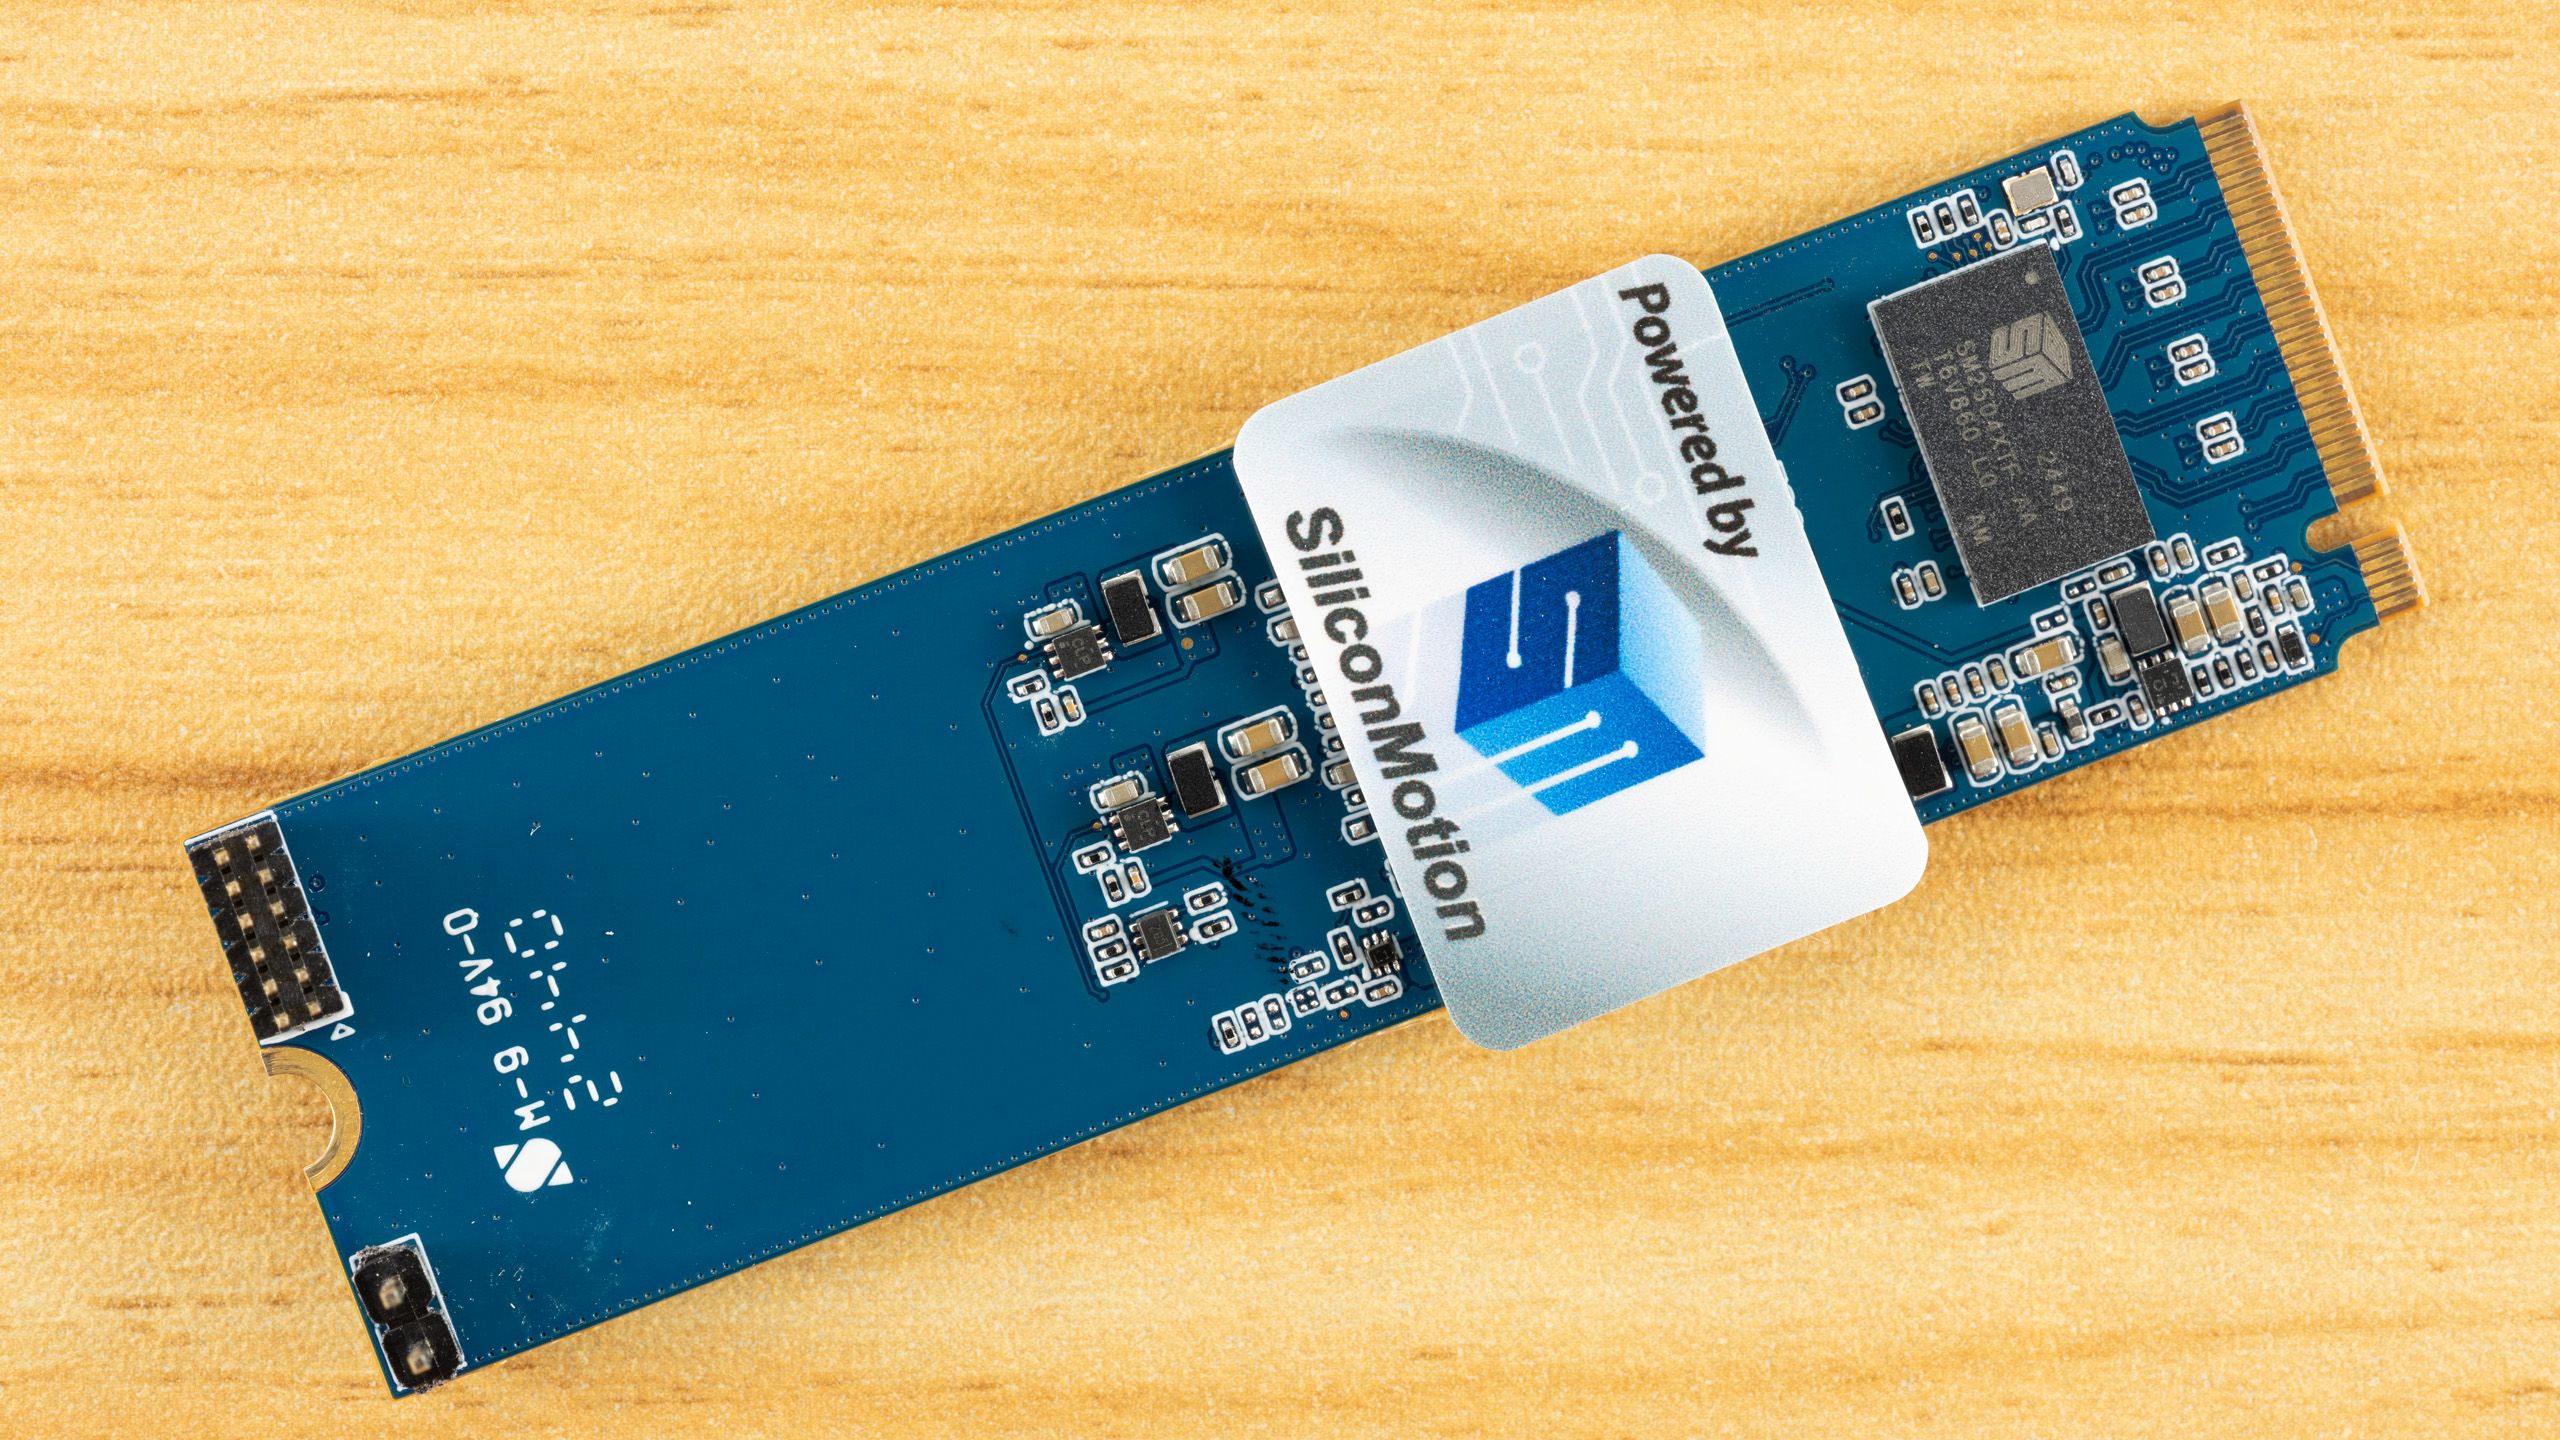
New Silicon Motion SM2524XT chip brings 14 GB/s to mainstream SSDs — 6nm DRAMless controller boasts heavy AI PC optimization and slashes KV cache latency
tomshardware.com/pc-components/ssds/new-silicon-motion-sm2524xt-chip-brings-14-gb-s-to-mainstream-ssds-6nm-dramless-controller-boasts-heavy-ai-pc-optimization-and-slashes-kv-cache-latency
github.com May 22
Asymmetric KV q8/q4 cache to preserve precision while reducing memory usage · ggml-org/llama.cpp · Discussion #23470
github.com/ggml-org/llama.cpp/discussions/23470
github.com Apr 05
GitHub - AlphaWaveSystems/tqai: TurboQuant KV cache compression for local LLM inference — 80% memory savings, near-zero quality loss on 8B+ models ...
github.com/AlphaWaveSystems/tqai

github.com Apr 02
GitHub - jhammant/Turbo1bit: Turbo1Bit: Combining 1-bit LLM weights (Bonsai) with TurboQuant KV cache compression for maximum inference efficiency. 4 ...
github.com/jhammant/Turbo1bit

github.com Mar 31
GitHub - Memoriant/dgx-spark-kv-cache-benchmark: KV cache quantization benchmarks on NVIDIA DGX Spark GB10 — three novel findings including the dequantization ...
github.com/Memoriant/dgx-spark-kv-cache-benchmark

Google's TurboQuant reduces AI LLM cache memory capacity requirements by at least six times — up to 8x performance boost on Nvidia H100 GPUs ...
tomshardware.com/tech-industry/artificial-intelligence/googles-turboquant-compresses-llm-kv-caches-to-3-bits-with-no-accuracy-loss

github.com Mar 24
GitHub - cenconq25/delta-compress-llm: Exploiting temporal coherence in LLM inference-- delta encoding for KV cache compression and weight-skip prediction ...
github.com/cenconq25/delta-compress-llm
github.com Mar 24
GitHub - samfurr/foveated_kv: Importance-adaptive mixed-precision KV cache compression for LLM inference on Apple Silicon.
github.com/samfurr/foveated_kv

github.com Mar 15
GitHub - joongom/mlx-soloheaven: Contribute to joongom/mlx-soloheaven development by creating an account on GitHub.
github.com/joongom/mlx-soloheaven

Nvidia’s new technique cuts LLM reasoning costs by 8x without losing accuracy: Nvidia researchers developed dynamic memory sparsification (DMS) ...
venturebeat.com/orchestration/nvidias-new-technique-cuts-llm-reasoning-costs-by-8x-without-losing-accuracy
trendforce.com Feb 12
[News] SK hynix Unveils AI Chip Architecture with HBF, Reportedly Boosts Performance per Watt by Up to 2.69×
trendforce.com/news/2026/02/12/news-sk-hynix-unveils-ai-chip-architecture-with-hbf-reportedly-boosts-performance-per-watt-by-up-to-2-69x/

Next