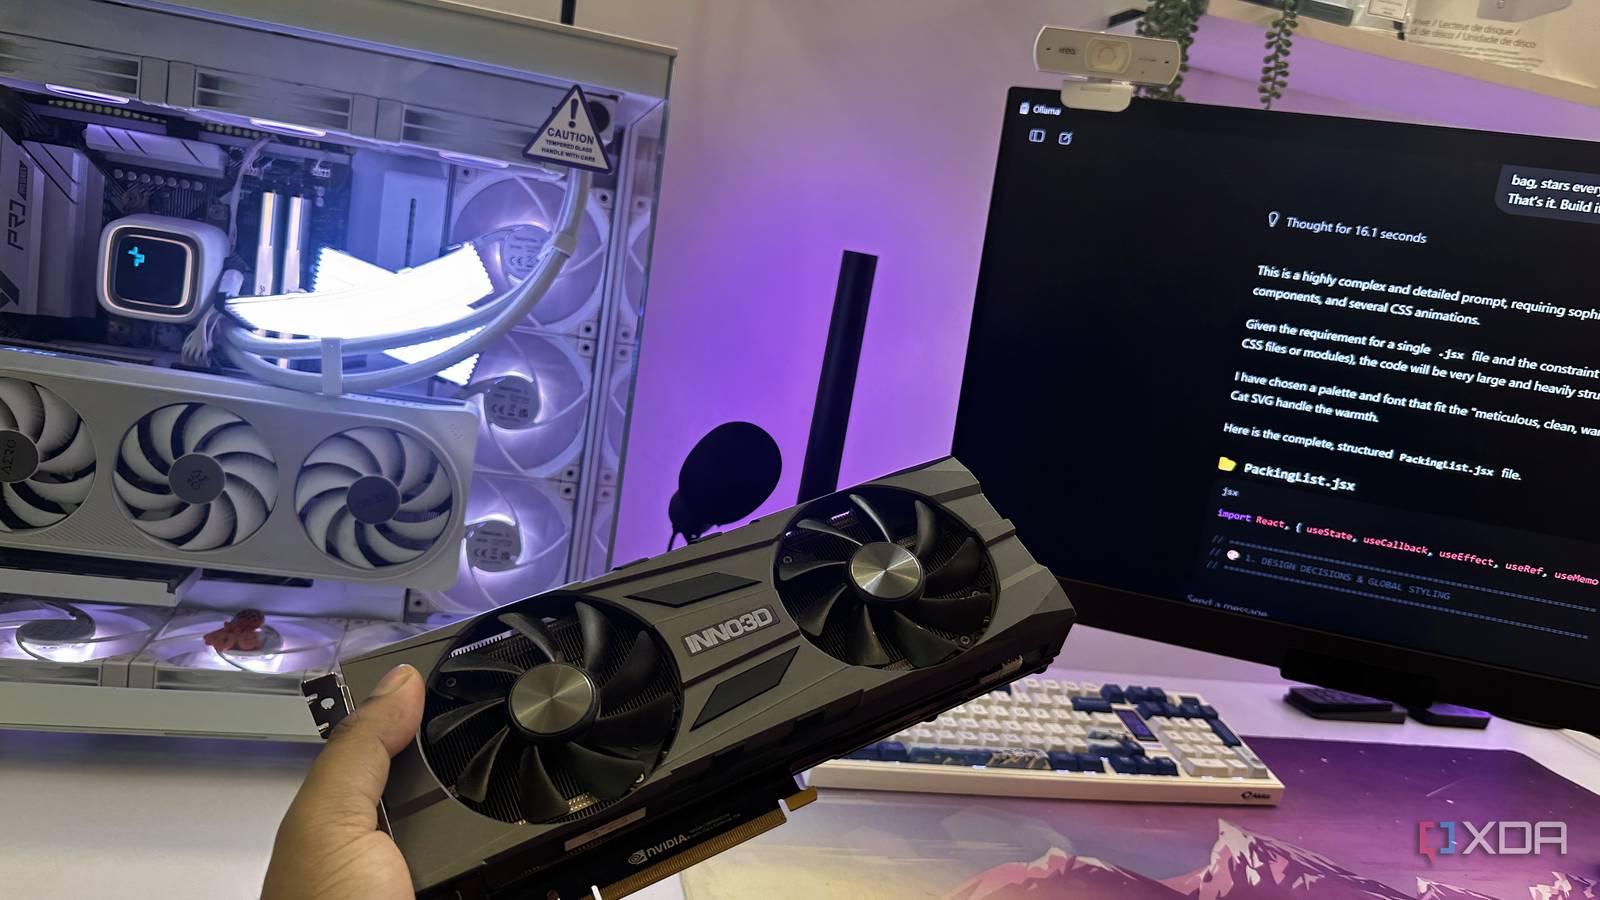
I added a second GPU just for local AI workloads, and it cost less than upgrading my main one
xda-developers.com/i-added-second-gpu-for-local-ai-cost-less-than-upgrading-main-one/
Story Details
| Last Updated | |
| Total Articles | 1 |
Main Topics

specialized electronic circuit; graphics accelerator

field that develops and studies software enabling machines to exhibit intelligent behavior
Similar to This
Previous

github.com Oct 28
GitHub - LLMPanel/llmpanel-oss: Deploy LLMs on any GPU, anywhere: Deploy LLMs on any GPU, anywhere. Contribute to LLMPanel/llmpanel-oss development by creating ...
github.com/LLMPanel/llmpanel-oss

github.com Oct 27
Qwen3.8 27B on one RTX 5090: comparing six engines across TTFT, prefill, decode, concurrency and tool tasks Show more
github.com Oct 24
Day 1 MiniMax-M3.1-Flash support in TensorSharp: GGUF, vision, tool calling, DSpark, and 8× A40 benchmarks Show more

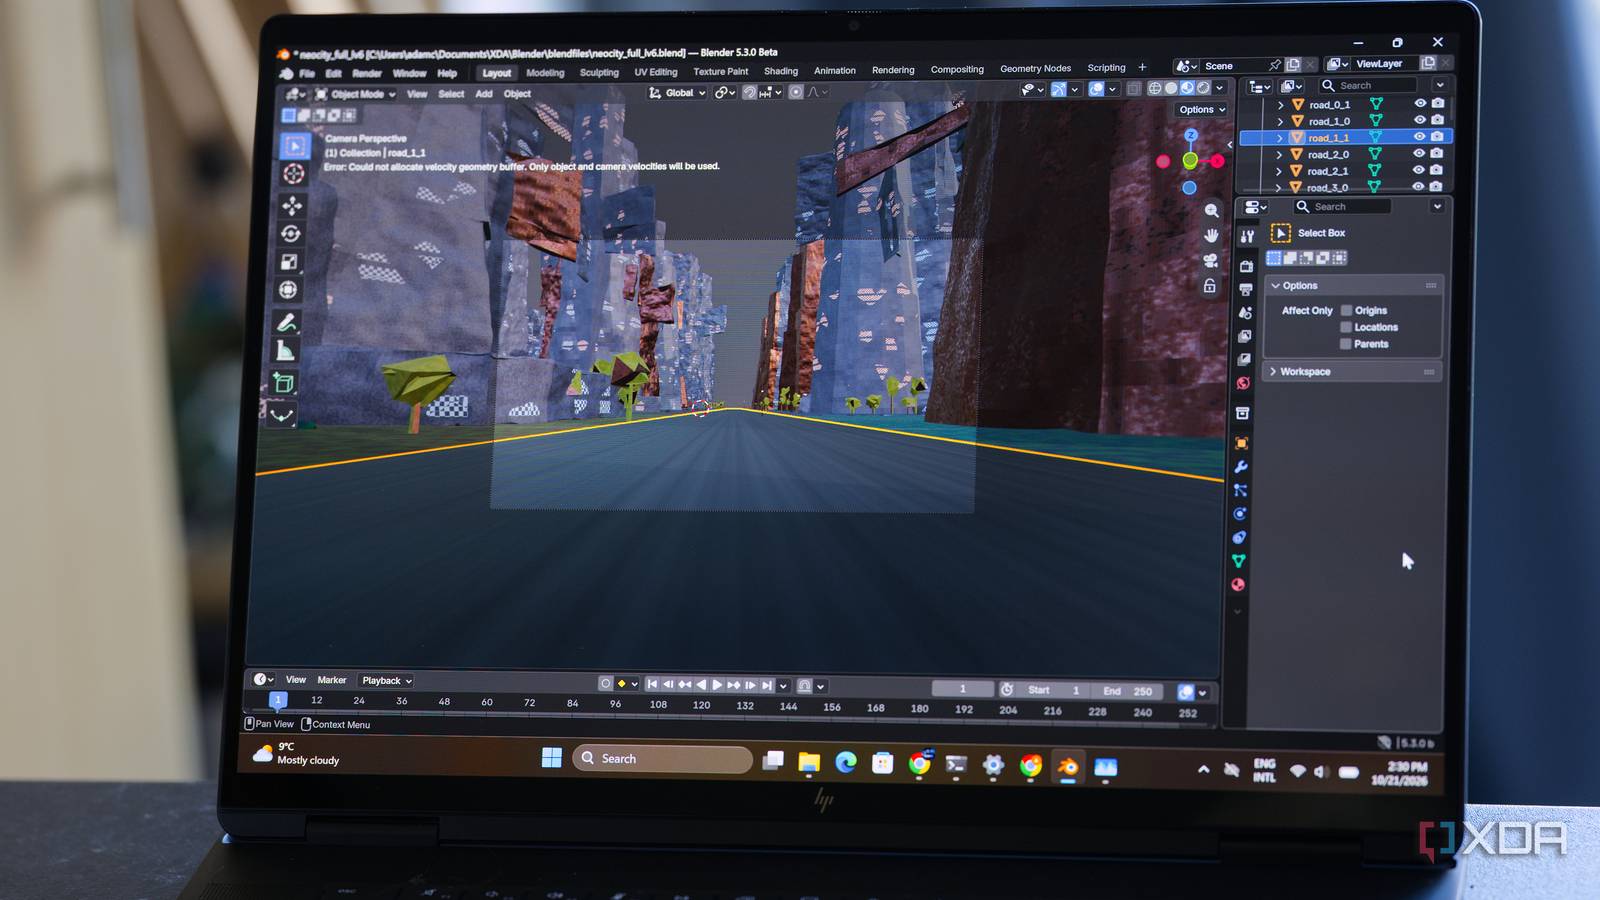
My RTX Spark laptop rendered a Blender scene too big for an RTX 5090, and a local LLM on the same machine built it
xda-developers.com/rtx-spark-laptop-rendered-blender-scene-too-big-rtx-5090-local-llm/
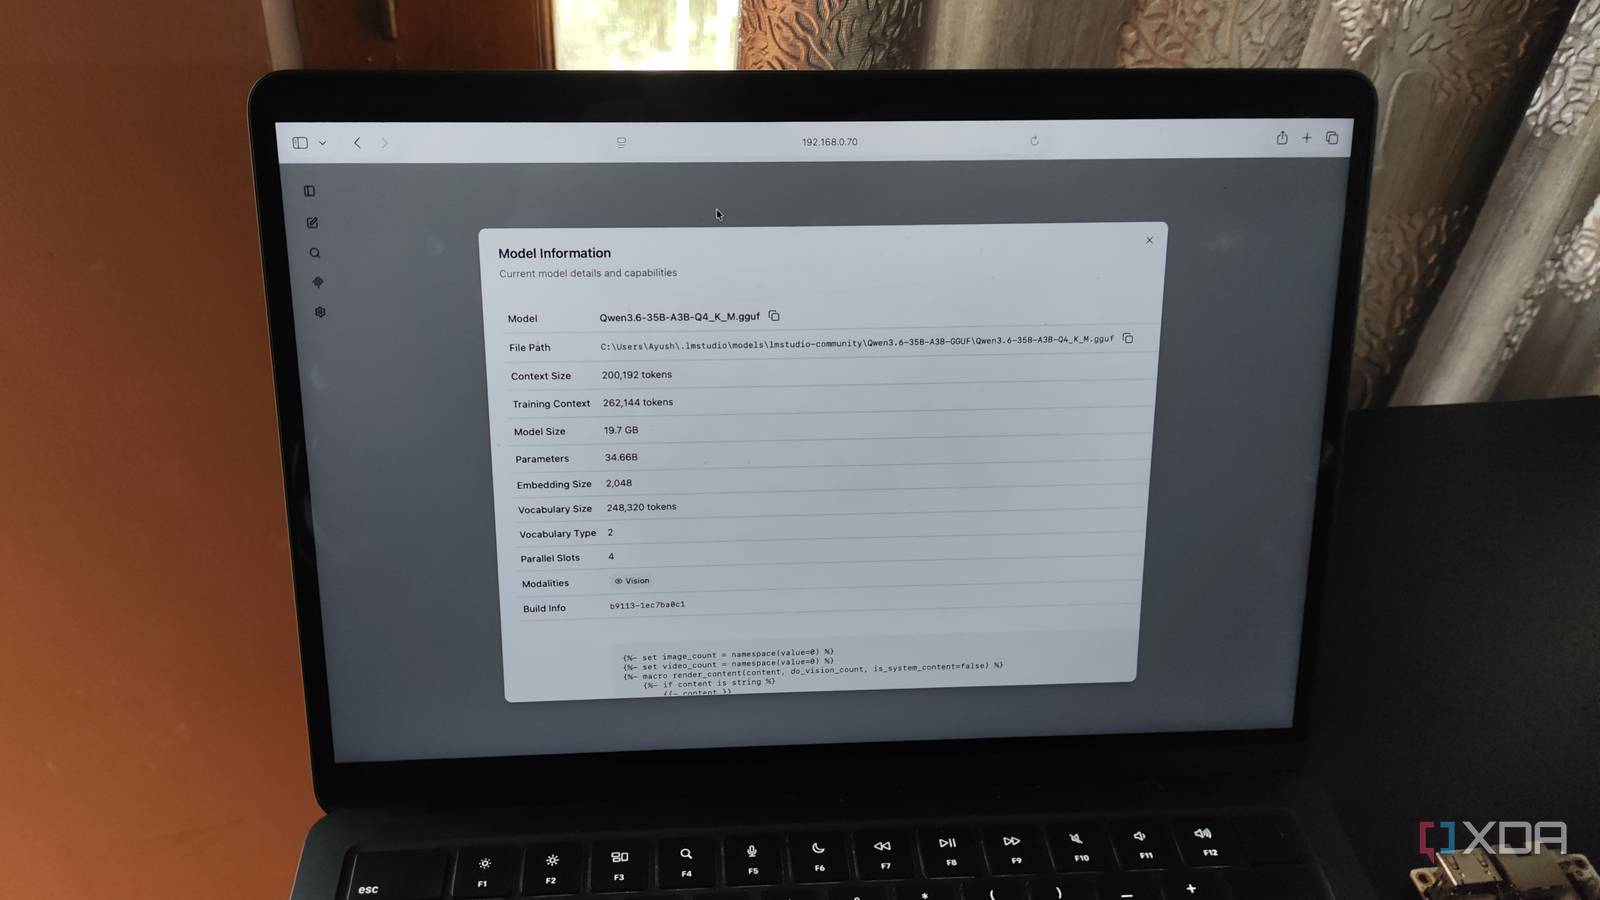
MoE models changed what "fits on my GPU" means, and most hardware advice hasn't caught up
xda-developers.com/moe-models-changed-what-fits-on-my-gpu-means-and-most-hardware-advice-hasnt-caught-up/
Running a local LLM on my AMD GPU was a lot easier than I expected: Unlocking more RAM for local models.
xda-developers.com/running-a-local-llm-on-my-amd-gpu-was-a-lot-easier-than-i-expected/
Running a local LLM on my AMD GPU was a lot easier than I expected: Unlocking more RAM for local models.
xda-developers.com/running-a-local-llm-on-my-amd-gpu-was-a-lot-easier-than-i-expected/
Old Nvidia GPUs with 24GB VRAM are crushing new cards at local AI inference, and here's why
xda-developers.com/old-nvidia-gpus-with-24gb-vram-are-crushing-new-cards-at-local-ai-inference-and-heres-why/
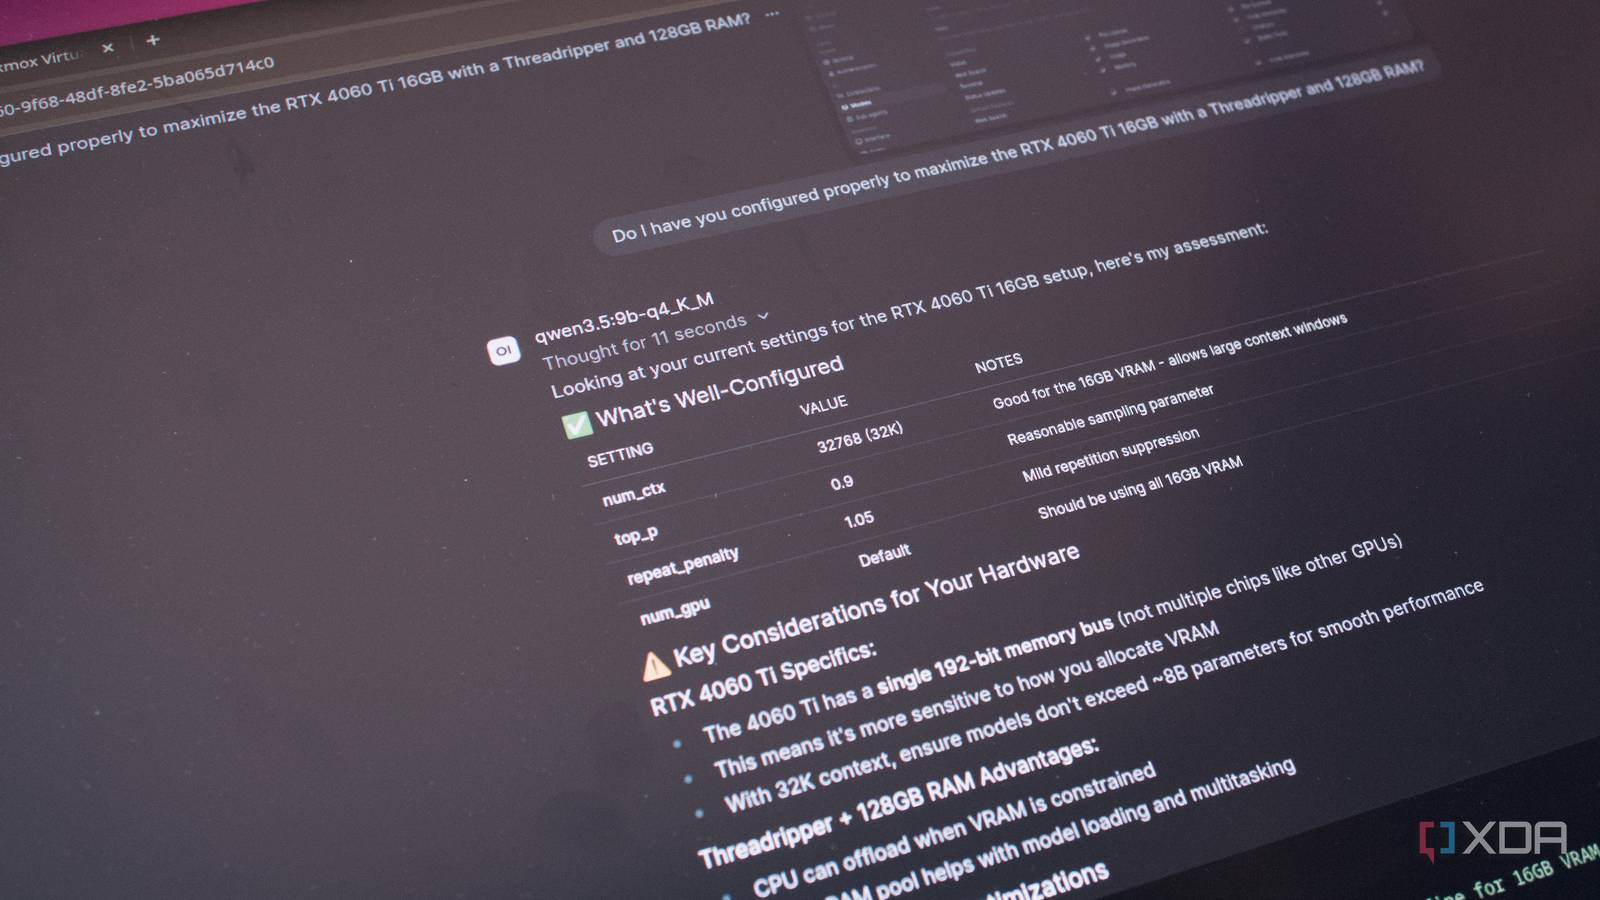
Two old GPUs I salvaged are doing more AI work than a brand new $2000 card, and I won't be upgrading anytime soon
xda-developers.com/two-old-gpus-are-doing-more-ai-work-than-a-brand-new-card/
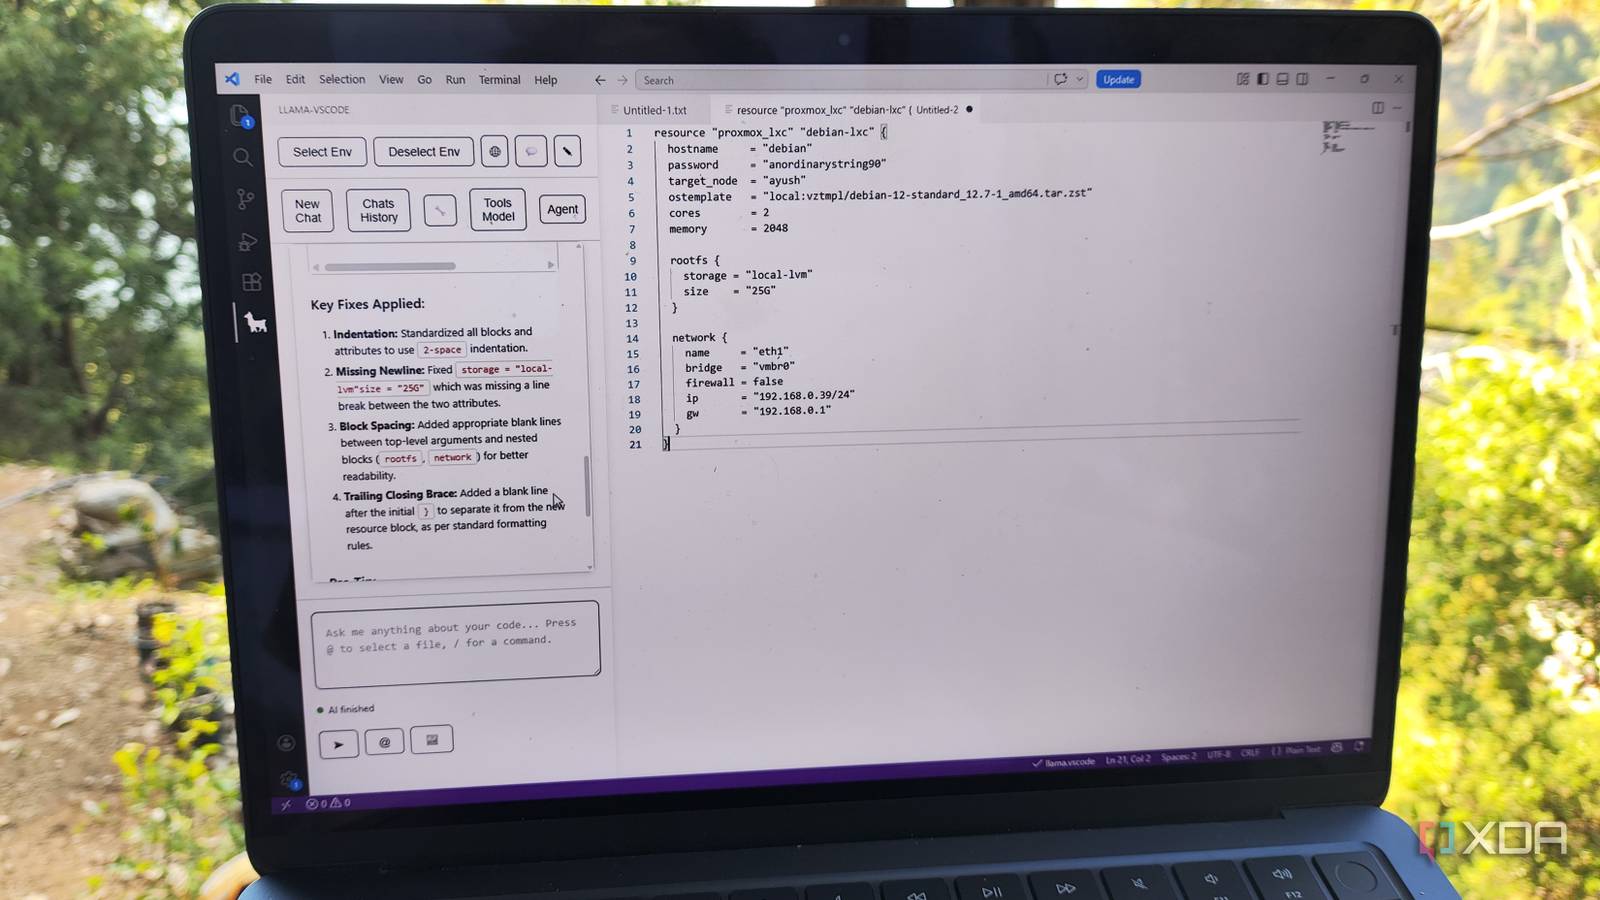
Two old GPUs I salvaged are doing more AI work than a brand new $2000 card, and I won't be upgrading anytime soon
xda-developers.com/two-old-gpus-are-doing-more-ai-work-than-a-brand-new-card/
I almost upgraded my GPU to run larger local LLMs, but this 8B model proved I didn't have to
xda-developers.com/almost-upgraded-gpu-to-run-larger-local-llms-but-8b-model-proved-i-didnt-have-to/
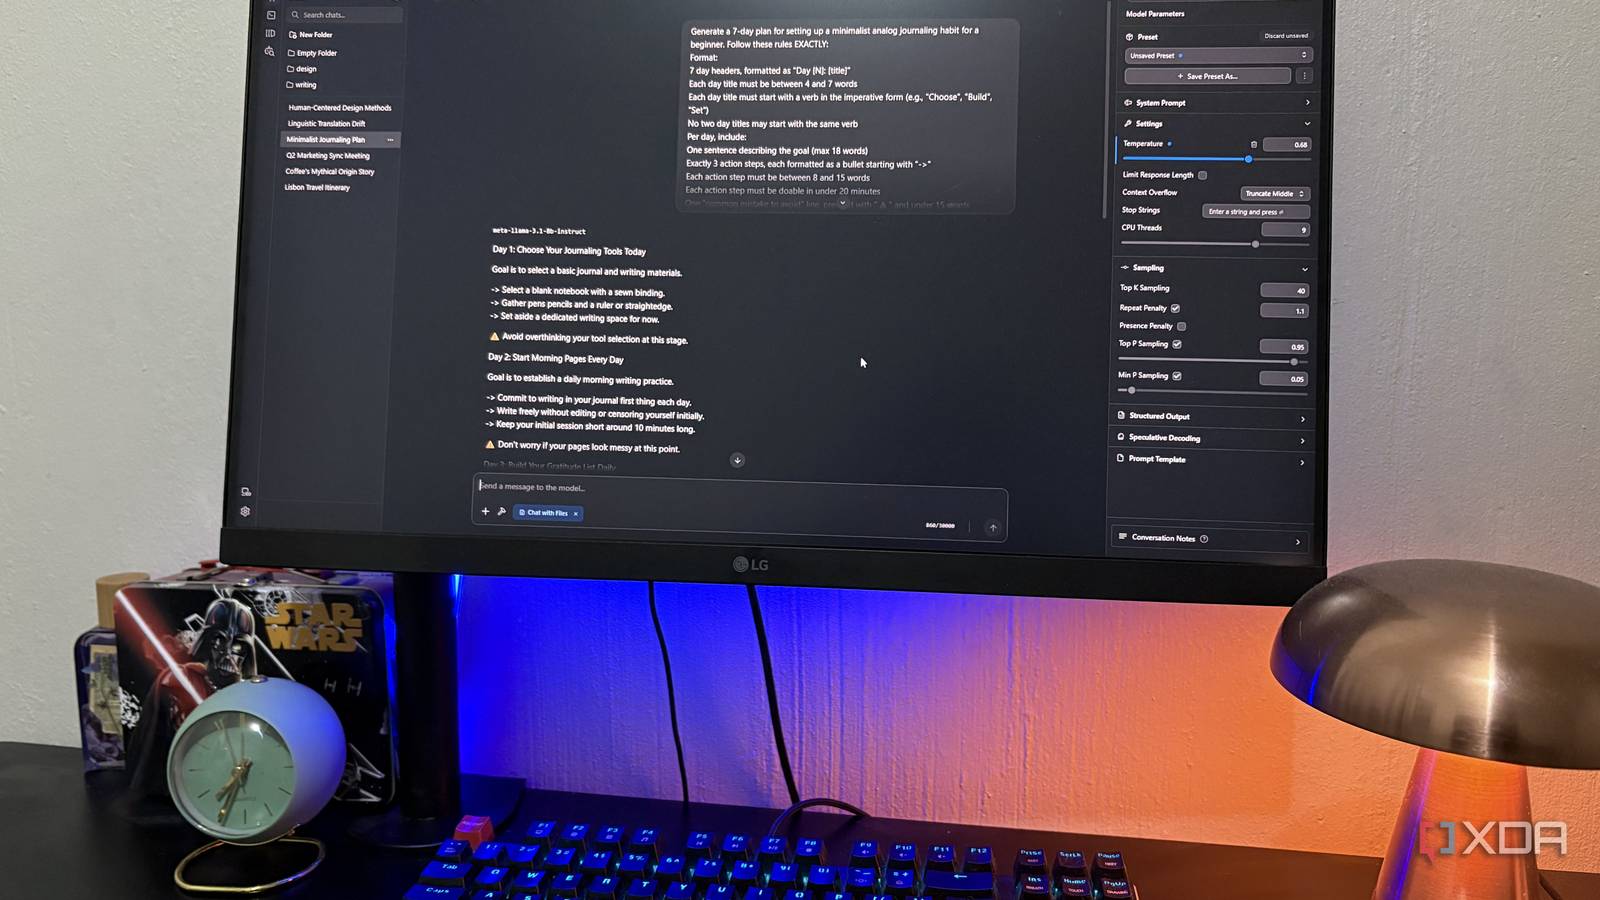
Two old GPUs I salvaged are doing more AI work than a brand new $2000 card, and I won't be upgrading anytime soon
xda-developers.com/two-old-gpus-are-doing-more-ai-work-than-a-brand-new-card/
Two old GPUs I salvaged are doing more AI work than a brand new $2000 card, and I won't be upgrading anytime soon
xda-developers.com/two-old-gpus-are-doing-more-ai-work-than-a-brand-new-card/
Two old GPUs I salvaged are doing more AI work than a brand new $2000 card, and I won't be upgrading anytime soon
xda-developers.com/two-old-gpus-are-doing-more-ai-work-than-a-brand-new-card/
I replaced cloud LLMs with local models running off a Proxmox LXC, and the performance trade-off was worth it
xda-developers.com/i-replaced-cloud-llms-with-local-models-running-off-a-proxmox-lxc/
github.com Mar 16
GitHub - Light-Heart-Labs/DreamServer: Turn your PC, Mac, or Linux box into a private AI server. LLM inference, chat UI, voice, agents, workflows, RAG ...
github.com/Light-Heart-Labs/DreamServer

A budget GPU can handle Plex transcoding and local AI at the same time: A remarkably efficient way to handle two very different workloads
xda-developers.com/a-budget-gpu-can-handle-plex-transcoding-and-local-ai-at-the-same-time/

Nvidia's new CPX GPU aims to change the game in AI inference — how the debut of cheaper and cooler GDDR7 memory could redefine AI inference infrastructure
tomshardware.com/pc-components/gpus/nvidias-new-cpx-gpu-aims-to-change-the-game-in-ai-inference-how-the-debut-of-cheaper-and-cooler-gddr7-memory-could-redefine-ai-inference-infrastructure

Next