
github.com Sep 23
GitHub - wnzn/semif-go: System One-style decision scoring over llama.cpp with multimodal input
github.com/wnzn/semif-go

Story Details
| Last Updated | |
| Total Articles | 1 |
Main Topics


in sports, an attempt by a player or team to immediately score a goal, rather than dribbling or passing
Similar to This
Previous
github.com Oct 18
GitHub - achyudh/llama.cpp: LLM inference in C/C++: LLM inference in C/C++. Contribute to achyudh/llama.cpp development by creating an account on GitHub.
github.com/achyudh/llama.cpp


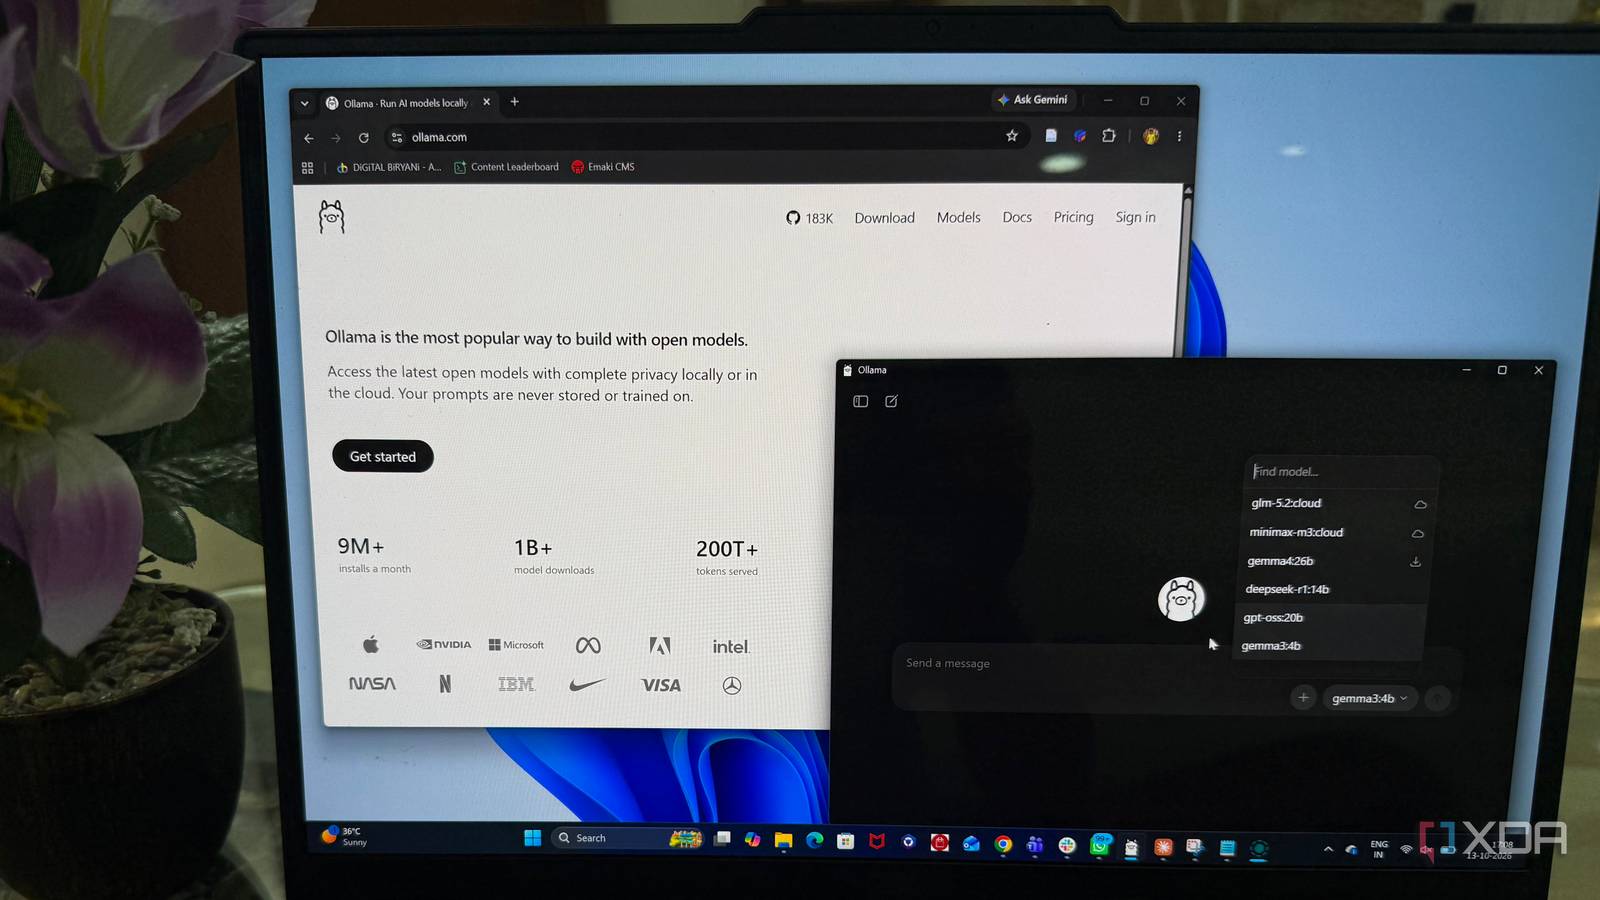
Ollama is the easiest way to start with local AI, and it's also the first thing I'd replace
xda-developers.com/ollama-easiest-way-start-with-local-ai-its-also-first-thing-id-replace/
github.com Oct 16
model : MTP support for Mellum2.1 by Xarbirus · Pull Request #30612 · ggml-org/llama.cpp
github.com/ggml-org/llama.cpp/pull/30612

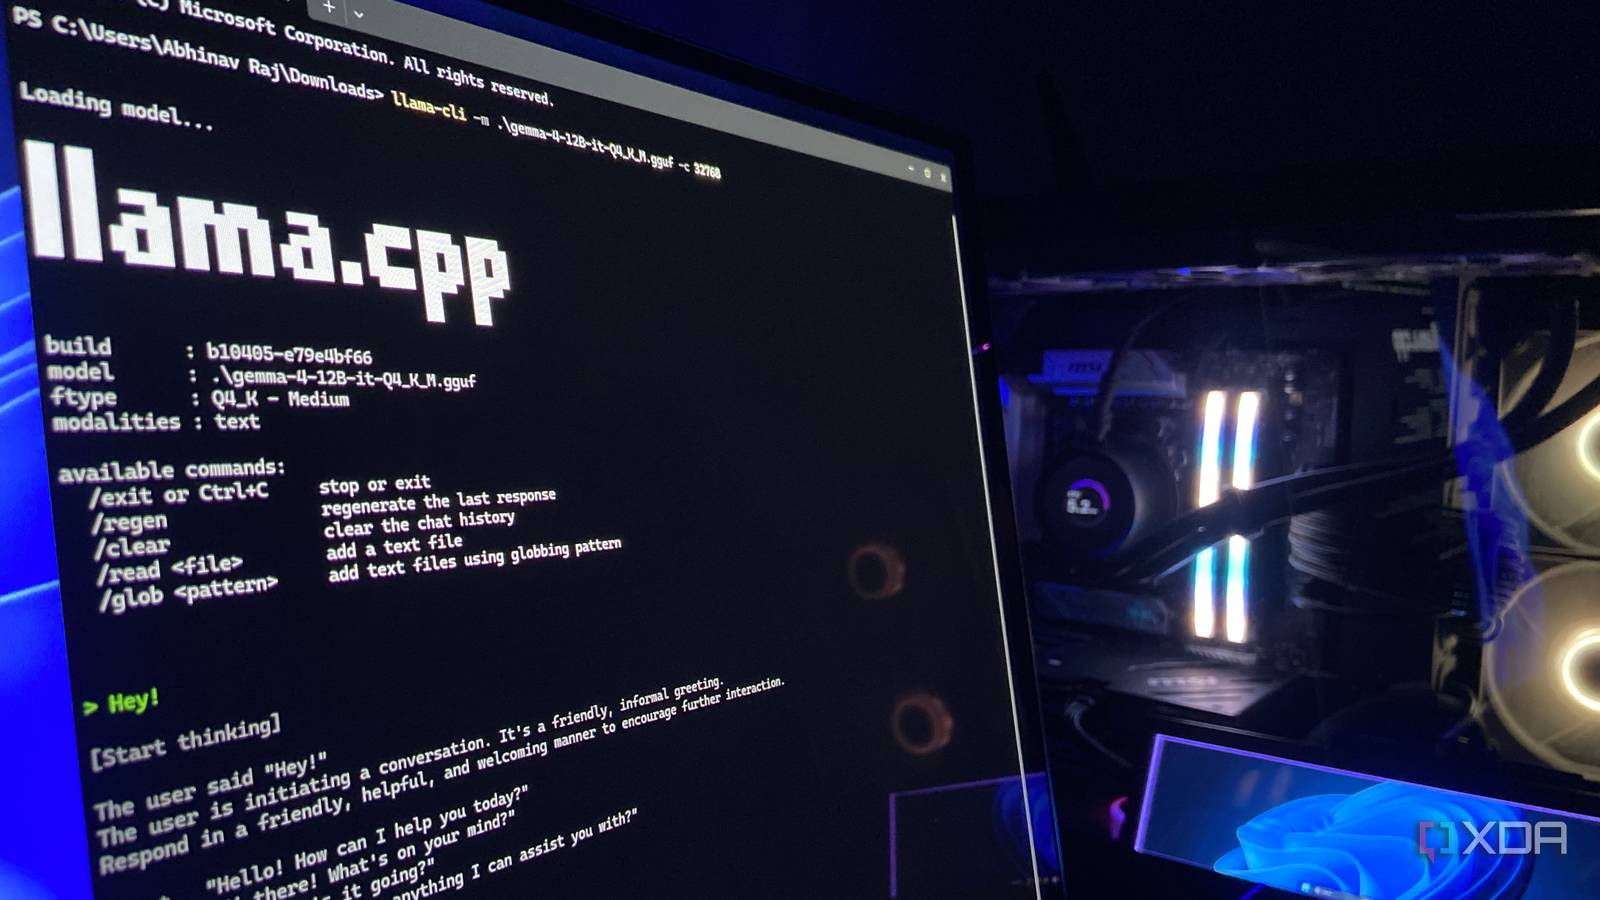
I moved my local models from Ollama to llama.cpp, and the reason I stayed has nothing to do with speed
xda-developers.com/i-moved-from-ollama-to-llamacpp-and-discovered-its-better-than-most-tools/
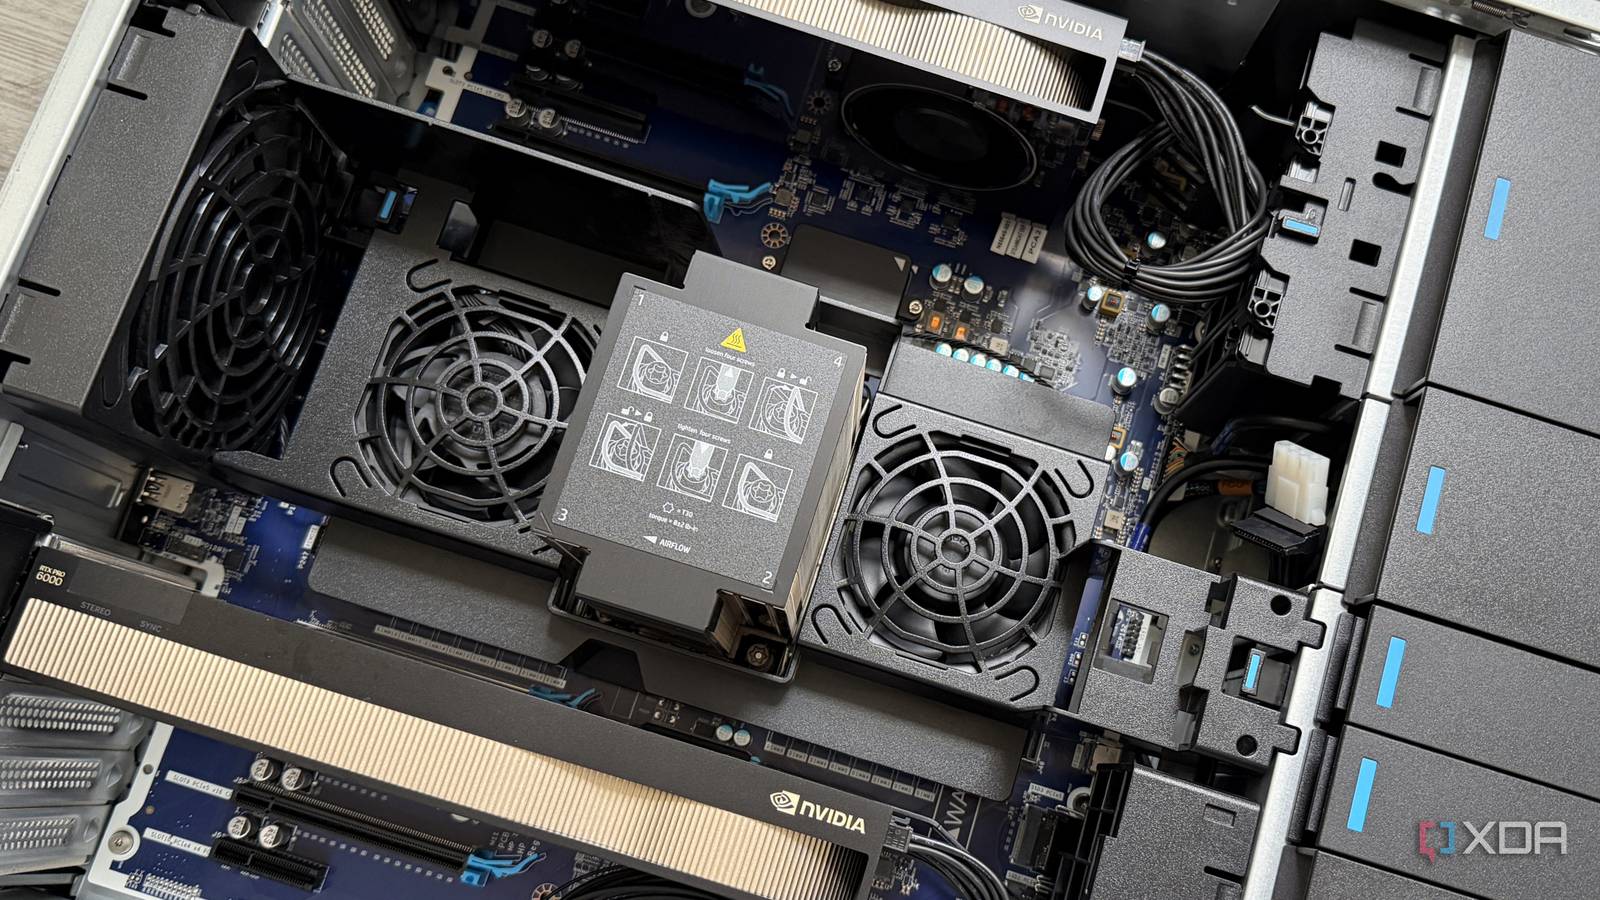
I ran GLM 5.3, a 744-billion-parameter model, on my home lab, and the frontier suddenly feels a lot closer
xda-developers.com/you-can-run-a-744b-model-on-your-own-hardware/
github.com Oct 13
GitHub - hardenedlinux/SonicBoom: Contribute to hardenedlinux/SonicBoom development by creating an account on GitHub.
github.com/hardenedlinux/SonicBoom

github.com Oct 11
Runtime support for Prism Bonsai 2 27B by bri-prism · Pull Request #29600 · ggml-org/llama.cpp
github.com/ggml-org/llama.cpp/pull/29600

github.com Sep 28
GitHub - solvingSteve/Gevva0: System 0 local decision gateway powered by Gemma 4. Direct logit scoring, KV-cache sequence branching ...
github.com/solvingSteve/Gevva0

I turned my old phone into a local LLM server, and it handles productivity tasks better than I expected
xda-developers.com/i-turned-my-old-phone-into-a-local-llm-server/

github.com Aug 27
GitHub - ccebelenski/localagents: MCP server that delegates Claude Code agent work to local models (llama.cpp / vLLM) on your own hardware
github.com/ccebelenski/localagents

github.com Aug 20
GitHub - mostlygeek/llama-swap: Reliable model swapping for any local OpenAI/Anthropic compatible server - llama.cpp, vllm, etc
github.com/mostlygeek/llama-swap

github.com Jul 30
GitHub - guarismo/armored-llama: Contribute to guarismo/armored-llama development by creating an account on GitHub.
github.com/guarismo/armored-llama

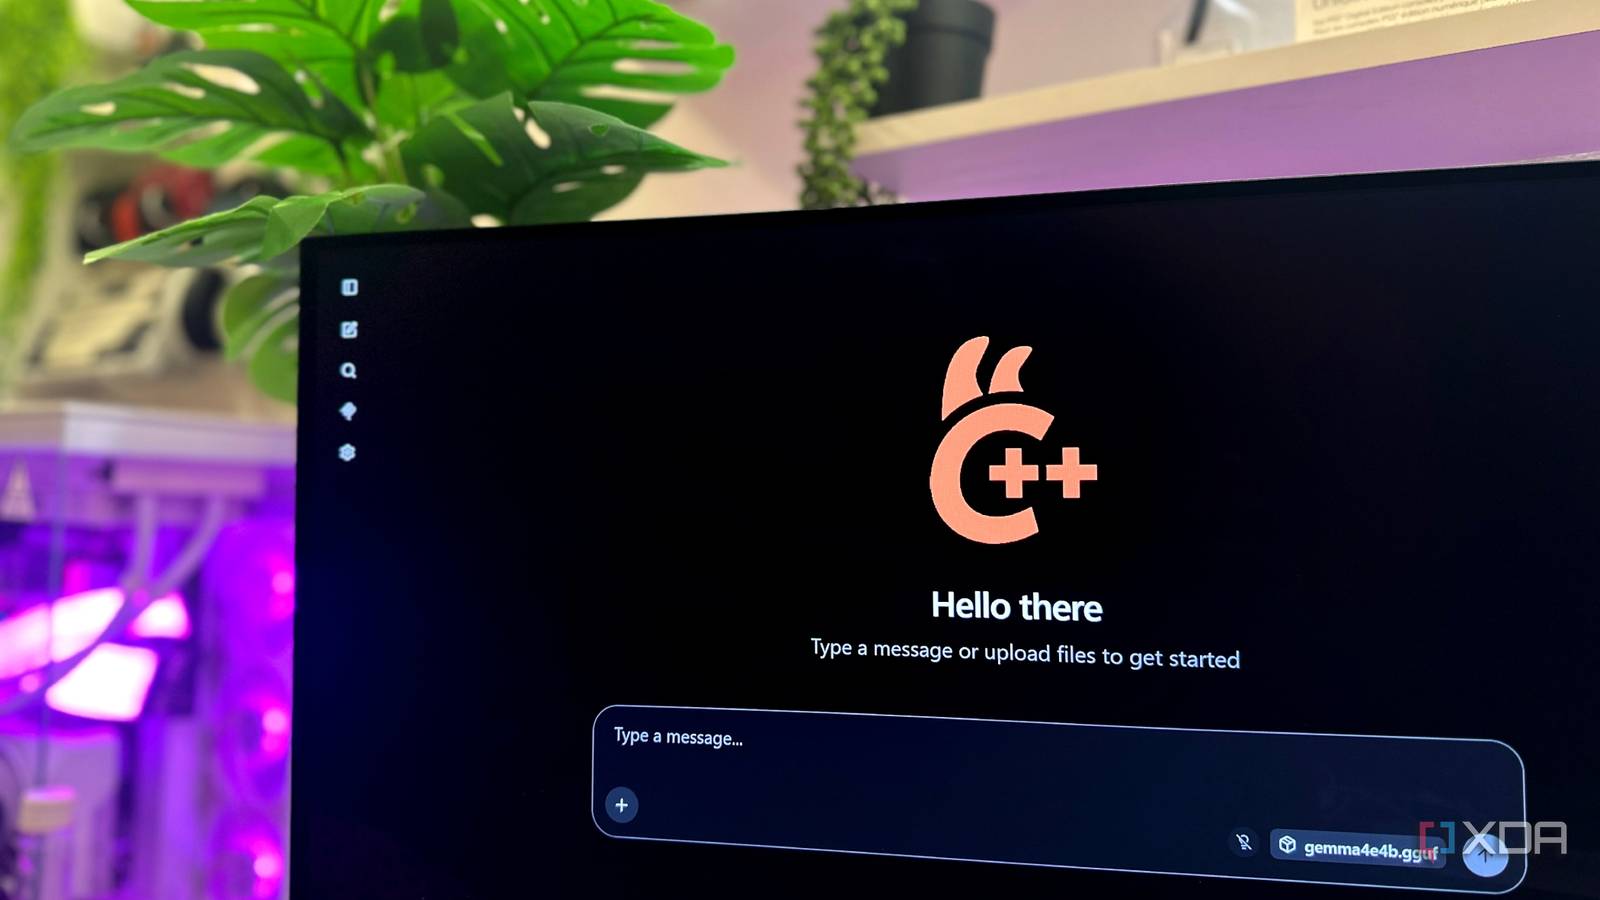
I finally ditched Ollama after using llama.cpp's WebUI, and I'm not going back anytime soon
xda-developers.com/i-ditched-ollama-after-using-llama-cpp-webui-and-im-not-going-back/
github.com Jun 19
llama.cpp/tools/server at master · ggml-org/llama.cpp: LLM inference in C/C++. Contribute to ggml-org/llama.cpp development by creating an account on GitHub.
github.com/ggml-org/llama.cpp/tree/master/tools/server
github.com May 21
server: fix checkpoints creation by jacekpoplawski · Pull Request #22929 · ggml-org/llama.cpp
github.com/ggml-org/llama.cpp/pull/22929

Next