
github.com Apr 13
GitHub - Aryagm/dflash-mlx: Exact speculative decoding on Apple Silicon, powered by MLX.
github.com/Aryagm/dflash-mlx
Story Details
| Last Updated | |
| Total Articles | 1 |
Main Topics


computing component that transparently stores data so that future requests for that data can be served faster
Similar to This
Previous

Computerworld Oct 17
Apple’s big AI week ends with Mac + Muse AI supercomputers: Apple and Meta bring Muse Spark Open to Mac Studio, MLX gets an upgrade and more.
computerworld.com/article/4236527/apples-big-ai-week-ends-with-mac-muse-ai-supercomputers.html

github.com Aug 06
GitHub - nicedreamzapp/nemotron-omni-mlx: Run NVIDIA's tri-modal Nemotron Omni (text+vision+audio) entirely on Apple Silicon — pure MLX runtime ...
github.com/nicedreamzapp/nemotron-omni-mlx

github.com Jun 20
GitHub - beamivalice/PonyExl3: Convert and Run Exl3 format LLM quant on Apple Silicon.
github.com/beamivalice/PonyExl3

github.com Jun 19
GitHub - ashhart/TensorFold: Fast, exact LLM decoding on Apple Silicon (MLX) behind an OpenAI-compatible endpoint
github.com/ashhart/TensorFold

github.com Jun 14
GitHub - igurss/mlx-chronos: Community-driven benchmark suite for MLX inference engines on Apple Silicon
github.com/igurss/mlx-chronos

github.com May 20
llama : add Gemma4 MTP by am17an · Pull Request #23398 · ggml-org/llama.cpp: LLM inference in C/C++. Contribute to ggml-org/llama.cpp development by creating an ...
github.com/ggml-org/llama.cpp/pull/23398

github.com Apr 15
DTree on MLX ... tiny win over DFlash on Qwen3.5-4B (M2)..
github.com/drbh/dtree-mlx
github.com Apr 15
GitHub - humanrouter/ddtree-mlx: Tree-based speculative decoding for Apple Silicon (MLX). ~10-15% faster than DFlash on code, ~1.5x over autoregressive ...
github.com/humanrouter/ddtree-mlx

github.com Apr 05
GitHub - AlphaWaveSystems/tqai: TurboQuant KV cache compression for local LLM inference — 80% memory savings, near-zero quality loss on 8B+ models ...
github.com/AlphaWaveSystems/tqai

github.com Apr 02
GitHub - bolyki01/localllm-gemma4-mlx: Local Gemma 4 E4B IT MLX bootstrap with OpenClaw integration notes
github.com/bolyki01/localllm-gemma4-mlx

github.com Apr 02
GitHub - ojus1/mlx-tinker: Tinker-compatible Backend on Apple Silicon: Tinker-compatible Backend on Apple Silicon. Contribute to ojus1/mlx-tinker development by ...
github.com/ojus1/mlx-tinker


Running local models on Macs gets faster with Ollama's MLX support: Apple Silicon Macs get a performance boost thanks to better unified memory usage.
arstechnica.com/apple/2026/03/running-local-models-on-macs-gets-faster-with-ollamas-mlx-support/

github.com Mar 30
GitHub - Anemll/anemll-flash-mlx: Contribute to Anemll/anemll-flash-mlx development by creating an account on GitHub.
github.com/Anemll/anemll-flash-mlx

github.com Mar 28
GitHub - Adam-Researchh/mlx-embed-finetune: Fine-tune embedding models with LoRA on Apple Silicon using MLX. 6-8x faster than PyTorch.
github.com/Adam-Researchh/mlx-embed-finetune

github.com Feb 28
GitHub - Wysie/wyoming-parakeet-mlx: Wyoming protocol server for Parakeet MLX speech-to-text on Apple Silicon
github.com/Wysie/wyoming-parakeet-mlx
github.com Feb 15
GitHub - moona3k/mlx-qwen3-asr: Qwen3-ASR speech recognition on Apple Silicon via MLX
github.com/moona3k/mlx-qwen3-asr

github.com Feb 10
GitHub - NTarek4741/mlx-engine: LM Studio Apple MLX engine: LM Studio Apple MLX engine . Contribute to NTarek4741/mlx-engine development by creating an account ...
github.com/NTarek4741/mlx-engine


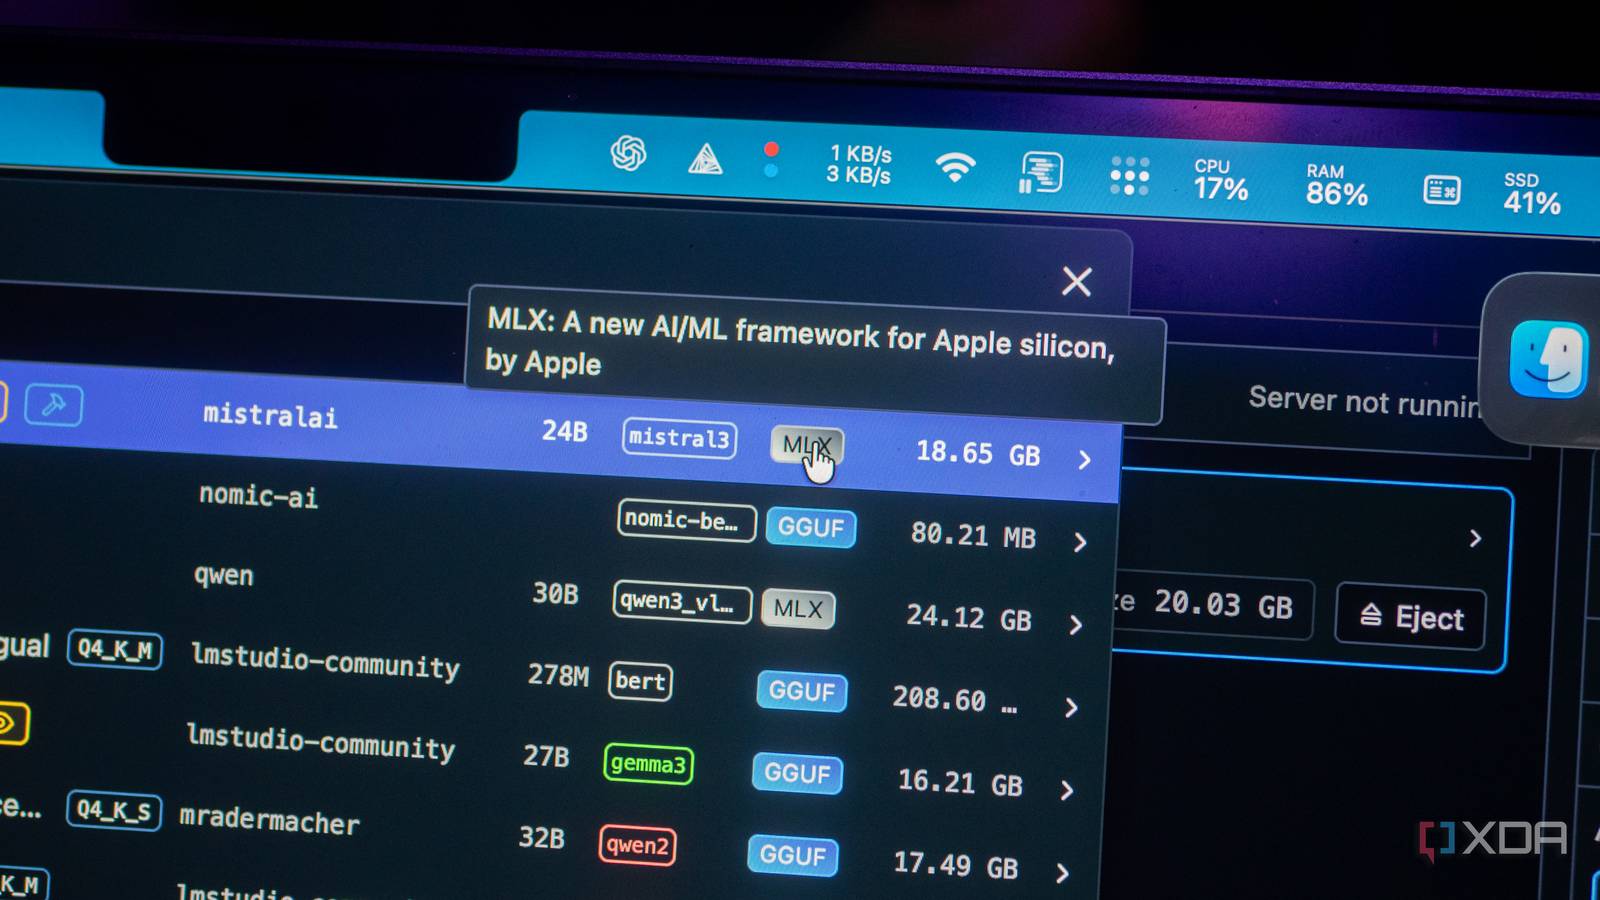
Apple has a sleeper advantage when it comes to local LLMs: Local LLMs thrive on Apple's hardware, and a huge part of it is thanks to MLX.
xda-developers.com/apple-sleeper-advantage-local-llms/
Next