8 local LLM settings most people never touch that fixed my worst AI problems:
If you run LLMs locally, these are the settings you need to be aware of.
xda-developers.com/local-llm-settings-most-people-never-touch/
Story Details
| Last Updated | |
| Total Articles | 1 |
Main Topics

electronic equipment intended for everyday use, typically in private homes


behavioral and cognitive process of selectively concentrating on a discrete aspect of information, whether deemed subjective or objective, while ignoring other perceivable information

computing component that transparently stores data so that future requests for that data can be served faster
Similar to This
Previous

MoE models changed what "fits on my GPU" means, and most hardware advice hasn't caught up
xda-developers.com/moe-models-changed-what-fits-on-my-gpu-means-and-most-hardware-advice-hasnt-caught-up/

github.com Oct 26
GitHub - madhusoodhans/model-cache-cleaner: Claude skill that finds and safely cleans storage used by local AI tools (LM Studio, Ollama, Hugging Face ...
github.com/madhusoodhans/model-cache-cleaner

Ollama is the easiest way to start with local AI, and it's also the first thing I'd replace
xda-developers.com/ollama-easiest-way-start-with-local-ai-its-also-first-thing-id-replace/
github.com Oct 07
GitHub - Chida82/sf-ds4-1flash: Contribute to Chida82/sf-ds4-1flash development by creating an account on GitHub.
github.com/Chida82/sf-ds4-1flash

Your local LLM is quietly wasting RAM on context you never use, and one setting gives it back
xda-developers.com/local-llm-wasting-ram-context-never-use-one-setting-gives-back/
I stopped my local LLM agent from running out of context, and now it handles what Claude Code does
xda-developers.com/stopped-my-local-llm-agent-from-running-out-of-context/
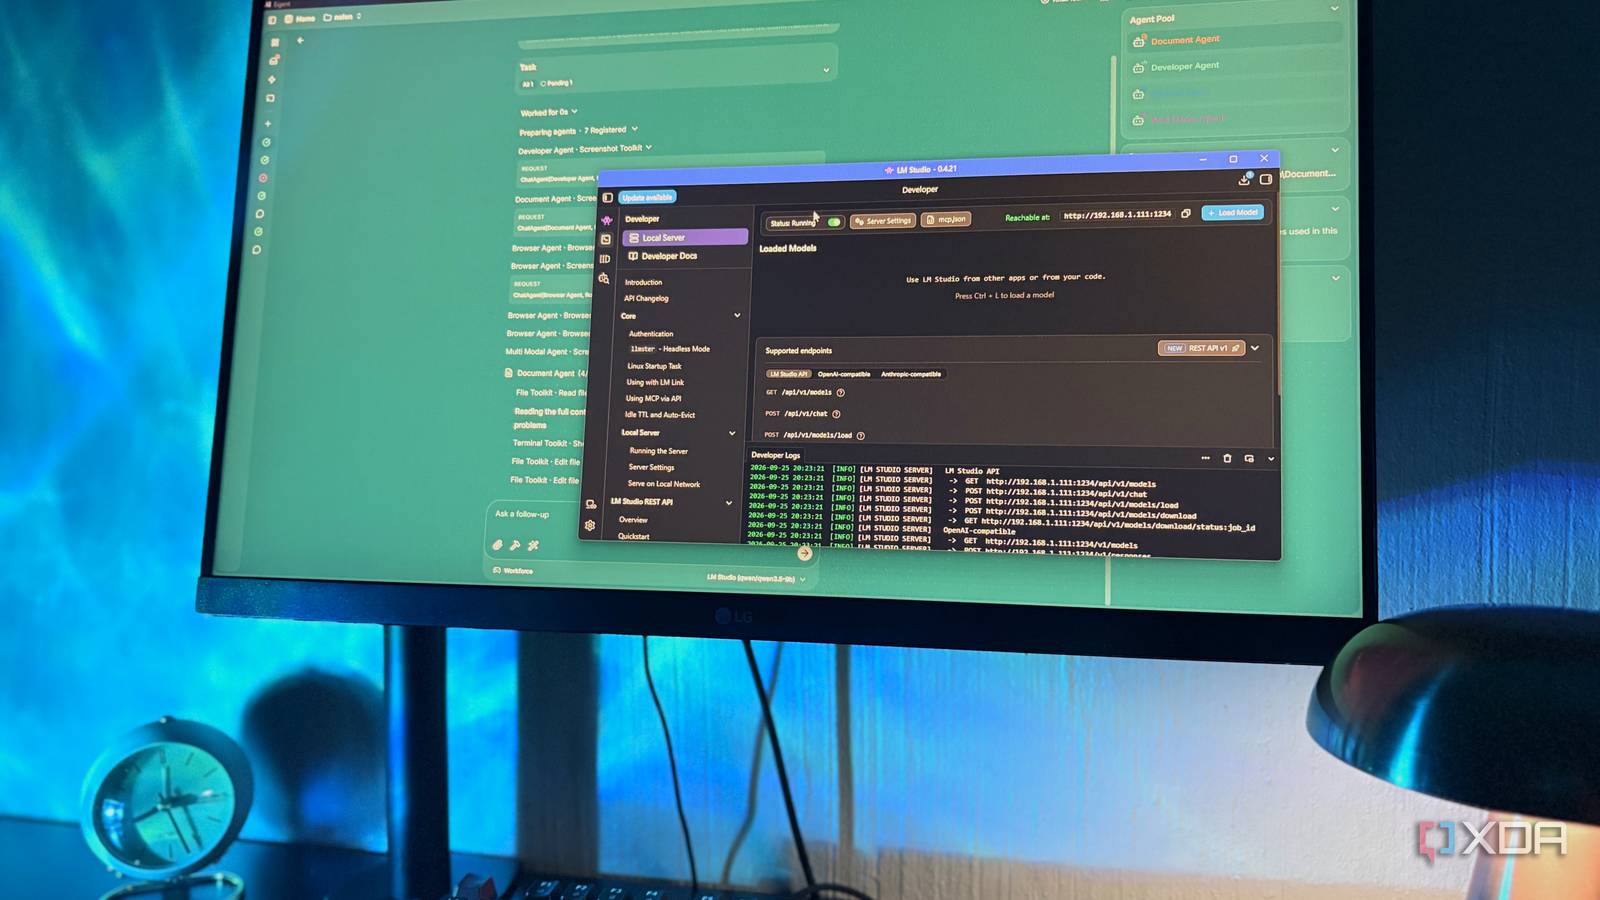
I stopped downloading bigger local models and started running two small ones at once
xda-developers.com/stopped-downloading-bigger-local-models-started-running-two-small-ones-at-once/
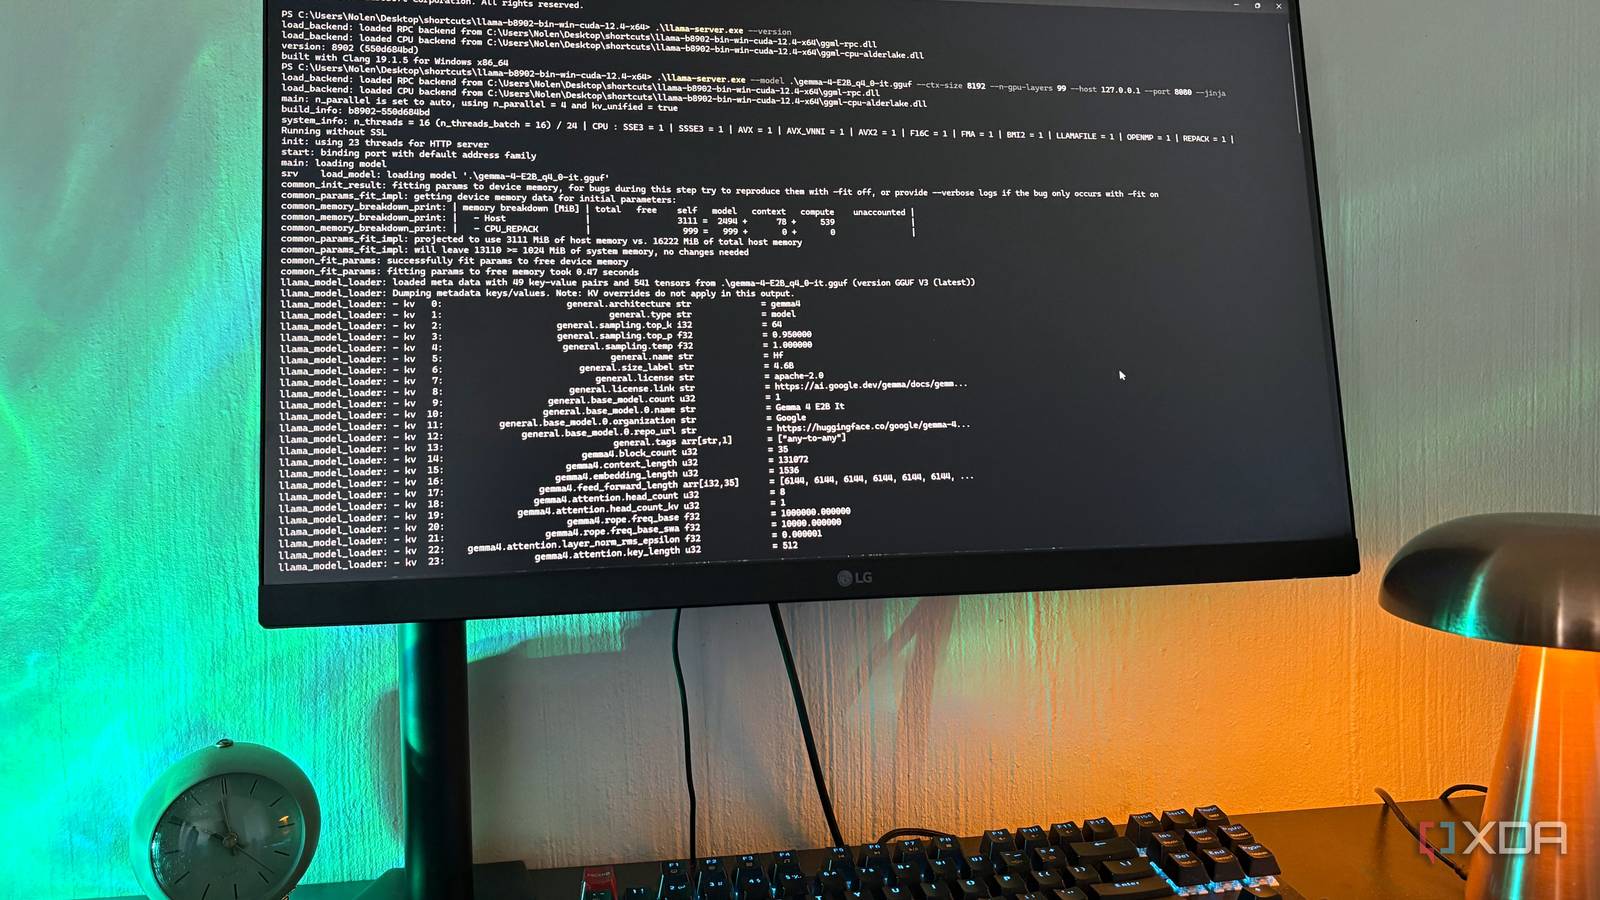
My local AI model was wasting VRAM by default, and changing one setting doubled its speed
xda-developers.com/my-local-ai-model-was-wasting-vram-by-default-and-lowering-one-setting-doubled-its-speed/
I check these 4 numbers before downloading a local AI model, and tokens per second is dead last
xda-developers.com/x-numbers-i-check-before-downloading-a-local-model-and-tokens-per-second-isnt-the-important-one/

6 settings I always change before running a local LLM: You might not need a different model, but better settings
xda-developers.com/settings-i-always-change-before-running-local-llm/

github.com Apr 28
GitHub - razvanneculai/litecode: CLI Tool for 8k context ai models: CLI Tool for 8k context ai models. Contribute to razvanneculai/litecode development by ...
github.com/razvanneculai/litecode

github.com Apr 15
GitHub - ParmesanParty/llama.cpp: Specialized fork for (relatively) fast single-GPU inference (in CUDA) using large MoE models that don't fit fully into ...
github.com/ParmesanParty/llama.cpp
github.com Feb 20
GitHub - peva3/SmarterRouter: SmarterRouter: An intelligent LLM gateway and VRAM-aware router for Ollama, llama.cpp, and OpenAI. Features semantic caching ...
github.com/peva3/SmarterRouter

github.com Feb 20
GitHub - elemein/agent-stoat: Local-first coding agent built with small models in mind and tight VRAM budgets.
github.com/elemein/agent-stoat

Next